Megatron
介绍 Megatron 框架的设计模式、训练流程以及代码实现细节
- 参考文章
训练一般流程
-
首先,需要初始化分布式环境、设置各种并行进程组
def initialize_distributed( tensor_model_parallel_size: int = 1, pipeline_model_parallel_size: int = 1 ) -> None: """ Initialize torch.distributed and Megatron-Core model parallel groups. Args: tensor_model_parallel_size: Number of GPUs for tensor model parallelism. pipeline_model_parallel_size: Number of GPUs for pipeline model parallelism. """ parallel_state.destroy_model_parallel() # Torch setup for distributed training rank: int = int(os.environ["RANK"]) # rank is the global rank across all processes world_size: int = int(os.environ["WORLD_SIZE"]) # world_size is the total number of processes across all nodes local_rank: int = int(os.environ["LOCAL_RANK"]) # local_rank is the rank of the process on the current node (0 to num_gpus_per_node-1) torch.cuda.set_device(local_rank) # Set the current GPU device based on local rank # Initialize the default process group for distributed training using NCCL backend, which is optimized for NVIDIA GPUs. # Each process will have a unique global rank and will know the total world size. torch.distributed.init_process_group( backend="nccl", rank=rank, world_size=world_size ) # Megatron core distributed training initialization parallel_state.initialize_model_parallel( tensor_model_parallel_size, pipeline_model_parallel_size ) initialize_distributed(tensor_model_parallel_size=2, pipeline_model_parallel_size=1) -
初始化模型并搬运到 GPU 上
def model_provider() -> GPTModel: """ Build and return a simple GPT model for demonstration. Returns: GPTModel: A small GPT model with 2 layers for testing. """ transformer_config: TransformerConfig = TransformerConfig( num_layers=12, hidden_size=4096, num_attention_heads=8, use_cpu_initialization=True, pipeline_dtype=torch.float32, ) gpt_model: GPTModel = GPTModel( config=transformer_config, transformer_layer_spec=get_gpt_layer_local_spec(), vocab_size=50257, max_sequence_length=_SEQUENCE_LENGTH, ) return gpt_model gpt_model: GPTModel = model_provider() device: torch.device = torch.device("cuda") gpt_model.to(device) -
上述代码中,初始化了一个隐藏层维度为 4096,共包含 8 个注意力头,12 层 Transformer 块的模型,词表大小为 50257,其参数量计算如下
- 注意力模块
- Q/K/V 对应的权重矩阵
3*H*H - 线性层
H*H
- Q/K/V 对应的权重矩阵
- MLP
- 升维映射
H*4H - 降维映射
4H*H
- 升维映射
- LN
- 每层两个 LN 计算
- 参数量为
2*(2*H)
- 一个 Transformer 层参数量为
12*H*H+4*H - L 层 Transformer 的参数量为
(12*H*H+4*H)*L - 嵌入层和输出投影
- 词表大小乘隐藏层维度
2*H*V
- 词表大小乘隐藏层维度
- 计算可以得到总参数量为
2,827,821,056,也即 2.8B 左右,其中模型主体参数量大约为 2.4B
- 注意力模块
-
下一步,使用 DDP 包裹模型以正确地进行梯度同步
config: TransformerConfig = gpt_model.config ddp_config: DistributedDataParallelConfig = DistributedDataParallelConfig( grad_reduce_in_fp32=False, overlap_grad_reduce=False, use_distributed_optimizer=False, ) gpt_model = DistributedDataParallel( config=config, ddp_config=ddp_config, module=gpt_model, ) -
然后初始化 Adam 优化器,初始化数据集
def get_train_data_iterator() -> Iterator: """ Create a mock dataset and return a data iterator. Returns: Iterator: Data iterator for training batches. """ if torch.distributed.is_available() and torch.distributed.is_initialized(): if torch.distributed.get_rank() == 0: compile_helpers() torch.distributed.barrier() else: compile_helpers() config: GPTDatasetConfig = GPTDatasetConfig( random_seed=0, sequence_length=_SEQUENCE_LENGTH, reset_position_ids=False, reset_attention_mask=False, eod_mask_loss=False, tokenizer=MegatronTokenizer.from_pretrained( metadata_path={"library": "null-text"}, vocab_size=_SEQUENCE_LENGTH, ), mid_level_dataset_surplus=0.005, ) datasets = BlendedMegatronDatasetBuilder( MockGPTDataset, [1000, None, None], lambda: True, config ).build() train_dataloader: DataLoader = DataLoader(datasets[0], batch_size=8, shuffle=True) train_iterator: Iterator = iter(train_dataloader) return train_iterator optim: Adam = Adam(gpt_model.parameters()) train_iterator: Iterator = get_train_data_iterator() -
get_forward_backward_func是 PP 的核心调度函数- 根据当前的并行配置(是否启用流水线并行、张量并行等),返回一个封装了前向传播 + 反向传播 逻辑的函数,让用户无需手动处理复杂的并行训练流程(如微批次切分、梯度同步、流水线调度等),只需调用这个函数就能完成一次完整的前向 + 反向计算
- 无流水线并行:返回基础的前向 + 反向函数,按批次执行完整的前向计算,再执行反向传播
- 有流水线并行:返回流水线调度函数(如 1F1B/Interleaved 1F1B 等),将批次切分为微批次(micro-batch),按流水线阶段依次执行不同微批次的前向 / 反向,提升 GPU 利用率
def get_forward_backward_func(pp_size: Optional[int] = None, vp_size: Optional[int] = None): """Retrieves the appropriate forward_backward function given the configuration of parallel_state. Returns a function that will perform all of the forward and backward passes of the model given the pipeline model parallel world size and virtual pipeline model parallel world size in the global parallel_state. Note that if using sequence parallelism, the sequence length component of the tensor shape is updated to original_sequence_length / tensor_model_parallel_world_size. The function returned takes the following arguments: forward_step_func (required): A function that takes a data iterator and a model as its arguments and return the model's forward output and the loss function. The loss function should take one torch.Tensor and return a torch.Tensor of loss and a dictionary of string -> torch.Tensor. A third argument, checkpoint_activations_microbatch, indicates that the activations for this microbatch should be checkpointed. A None value for this argument indicates that the default from the configuration should be used. This is used when the num_microbatches_with_partial_activation_checkpoints is used. For example: def loss_func(loss_mask, output_tensor): losses = output_tensor.float() loss_mask = loss_mask.view(-1).float() loss = torch.sum(losses.view(-1) * loss_mask) / loss_mask.sum() # Reduce loss for logging. averaged_loss = average_losses_across_data_parallel_group([loss]) return loss, {'lm loss': averaged_loss[0]} def forward_step(data_iterator, model): data, loss_mask = next(data_iterator) output = model(data) return output, partial(loss_func, loss_mask) forward_backward_func(forward_step_func=forward_step, ...) data_iterator (required): an iterator over the data, will be passed as is to forward_step_func. Expected to be a list of iterators in the case of interleaved pipeline parallelism. model (required): the actual model. Expected to be a list of modules in the case of interleaved pipeline parallelism. Must be a (potentially wrapped) megatron.core.models.MegatronModule. num_microbatches (int, required): The number of microbatches to go through seq_length (int, required): Sequence length of the current global batch. If this is a dual-stack transformer, this is the encoder's sequence length. This is ignored if variable_seq_lengths in the config is True. Otherwise, each microbatch in the current global batch size must use this sequence length. micro_batch_size (int, required): The number of sequences in a microbatch. decoder_seq_length (int, optional): The sequence length for the decoder in a dual-stack transformer. This is ignored for a single-stack transformer. forward_only (optional, default = False): Perform only the forward step. collect_non_loss_data (optional, bool, default=False): TODO. first_val_step (bool, optional): Is the first step of the validation phase. Used by Transformer Engine modules to only update their fp8 weights only on the first validation step. adjust_tensor_shapes_fn (Callable, optional): A function that adjusts the receive and send tensor shapes. Only applicable in forward_backward_pipelining_without_interleaving for now. Takes in a list of receive shapes and a list of send shapes and returns the adjusted respective list of shapes. Thus it is not used in the other forward-backward functions which have different shape handling. force_all_reduce (bool, optional): If true, force use of all-reduce for gradient reduction instead of reduce-scatter (if using distributed optimizer) in this iteration to ensure all data-parallel ranks have fully reduced gradients. This is useful for easier wgrad saving (can just inspect DP replica 0 to get full set of wgrads for entire model). Args: pp_size (Optional[int]): Pipeline model parallel size to use. vp_size (Optional[int]): Virtual pipeline model parallel size to use. If both pp_size and vp_size are None, both values fall back to parallel_state. Otherwise, provided values are used as-is and None is treated as an explicit input. """ if pp_size is None and vp_size is None: pp_size = parallel_state.get_pipeline_model_parallel_world_size() vp_size = parallel_state.get_virtual_pipeline_model_parallel_world_size() if pp_size > 1: if vp_size is not None: forward_backward_func = forward_backward_pipelining_with_interleaving else: forward_backward_func = forward_backward_pipelining_without_interleaving else: forward_backward_func = forward_backward_no_pipelining return forward_backward_func forward_backward_func: Callable[..., Dict[str, Any]] = get_forward_backward_func() -
接下来,定义 forward_step_func 计算模型输出并返回 loss 计算函数
def forward_step_func( data_iterator: Iterator, model: torch.nn.Module ) -> Tuple[torch.Tensor, Callable]: """ Forward step function that computes model output and returns loss function. Args: data_iterator: Iterator providing training batches. model: The GPT model to train. Returns: Tuple of (output_tensor, loss_function) where loss_function is a partial function that will compute the final loss when called. """ def loss_func( loss_mask: torch.Tensor, output_tensor: torch.Tensor ) -> Tuple[torch.Tensor, Dict[str, torch.Tensor]]: losses: torch.Tensor = output_tensor.float() loss_mask = loss_mask.view(-1).float() loss: torch.Tensor = torch.sum(losses.view(-1) * loss_mask) / loss_mask.sum() # If you have data parallel reduce loss across data parallel groups. # If pipeline parallel, loss computation is done only in last stage. return loss, {"lm loss": loss} data: Dict[str, torch.Tensor] = next(data_iterator) tokens: torch.Tensor = data["tokens"].to(device) attention_mask: torch.Tensor = data["attention_mask"].to(device) position_ids: torch.Tensor = data["position_ids"].to(device) labels: torch.Tensor = data["labels"].to(device) loss_mask: torch.Tensor = data["loss_mask"].to(device) output_tensor: torch.Tensor = model( tokens, position_ids, attention_mask, labels=labels ) return output_tensor, partial(loss_func, loss_mask) -
然后就可以开始进行训练循环,这里设置的 _SEQUENCE_LENGTH 为 1024
- 首先清空优化器的梯度值
- 进行一次前向传播和反向传播梯度计算
- 然后调用 finalize_model_grads 来 all-reduce TP 中的非 TP 并行梯度 / DP 中的所有梯度
- 优化器根据梯度更新参数
# Running the model for 5 iterations for iteration in range(5): optim.zero_grad() losses_reduced: Dict[str, Any] = forward_backward_func( forward_step_func=forward_step_func, data_iterator=train_iterator, model=gpt_model, num_microbatches=1, seq_length=_SEQUENCE_LENGTH, micro_batch_size=8, decoder_seq_length=_SEQUENCE_LENGTH, forward_only=False, ) # Finalize model gradients: all-reduce across DP and TP groups. # This synchronizes gradients for non-tensor-parallel parameters (e.g., LayerNorm) # across tensor parallel ranks and all gradients across data parallel ranks. finalize_model_grads([gpt_model]) optim.step() print(f"Iteration {iteration}: Losses reduced: {losses_reduced}") -
执行完训练循环后,保存模型检查点
# Saving the model ckpt_path: str = os.getcwd() + "/ckpt" Path(ckpt_path).mkdir(exist_ok=True) save_distributed_checkpoint(gpt_model=gpt_model, checkpoint_path=ckpt_path) # Loading the model gpt_model = load_distributed_checkpoint( gpt_model=gpt_model, checkpoint_path=ckpt_path ) gpt_model.to(device) print("Successfully loaded the model") -
在上述过程中,还使用了 cuda 的显存记录工具来保存整个训练过程中的显存历史快照
# Start recording memory history
torch.cuda.memory._record_memory_history(max_entries=100000)

# ...
# Training logic ...
# ...

# Export memory history for rank 0
if torch.distributed.get_rank() == 0:
    try:
        torch.cuda.memory._dump_snapshot("ckpt/memory_snapshot.pickle")
        print("Successfully dumped memory snapshot to memory_snapshot.pickle")
    except Exception as e:
        print(f"Failed to dump memory snapshot: {e}")

        # Stop recording memory history
        torch.cuda.memory._record_memory_history(None)
Megatron 的设计模式
-
在 Megatron 中,模型、数据集划分逻辑、前向计算逻辑等都以 provider 的形式传入 pretrain 函数,pretrain 函数会进行以下步骤
- initialize_megatron:初始化 Megatron
- setup_model_and_optimizer:通过 model_provider 设置模型、优化器、学习率调度器
- build_train_valid_test_data_iterators:通过 train_valid_test_dataset_provider 设置 train/val/test 数据集
- train:通过 forward_step_func 执行训练循环
- save_checkpoint:保存 checkpoint
- evaluate_and_print_results:执行验证 / 测试
- 结束训练并清理资源
-
pretrain 的关键参数
- model_provider:model_provider 返回的应该是 vanilla 模型,没有进行任何混合精度操作、DDP 封装的在 CPU 上的模型
- get_embedding_ranks:传入 PP 并行组,返回应该包含词向量表的那些 PP rank,一般指模型的输入嵌入层和输出嵌入层,默认返回 PP 并行组的第一个和最后一个 stage
- get_position_embedding_ranks:同 get_embedding_ranks
- forward_step_func:输入 data_iterator 和 model,返回损失和 metrics
- process_non_loss_data_func:用于 Tensorboard 记录、输出图像、dump tensor 等
- inprocess_call_wrapper:用于进程内重启容错
-
在 pretrain 中,有一些逻辑用于收集训练中的各种指标
_STARTUP_TIMESTAMPS['pretrain_entry'] = time.time():统计启动时间,方便计算初始化时间、任务调度延迟等- 收集 wandb 日志
-
整个训练流程如下
pretrain
 │
 ├─ 初始化时间统计
 ├─ fault tolerance setup
 │
 ├─ initialize_megatron
 │    ├─ 初始化 distributed
 │    ├─ 初始化 parallel groups
 │    └─ 初始化 args/timers
 │
 ├─ set_jit_fusion_options
 │
 ├─ setup_model_and_optimizer
 │    ├─ build model
 │    ├─ wrap parallel
 │    ├─ optimizer
 │    └─ lr scheduler
 │
 ├─ build_train_valid_test_data_iterators
 │
 ├─ train()
 │    ├─ forward_step
 │    ├─ backward
 │    ├─ optimizer step
 │    └─ logging
 │
 ├─ save_checkpoint
 │
 ├─ evaluate(valid)
 │
 ├─ evaluate(test)
 │
 ├─ finalize checkpoint
 │
 └─ shutdown
初始化 Megatron
-
初始化 Megatron 做了如下事:
- 定义模型的切割框架
- 在此框架上,初始化进程,分配 GPU,设置进程组(DP/TP/PP)
-
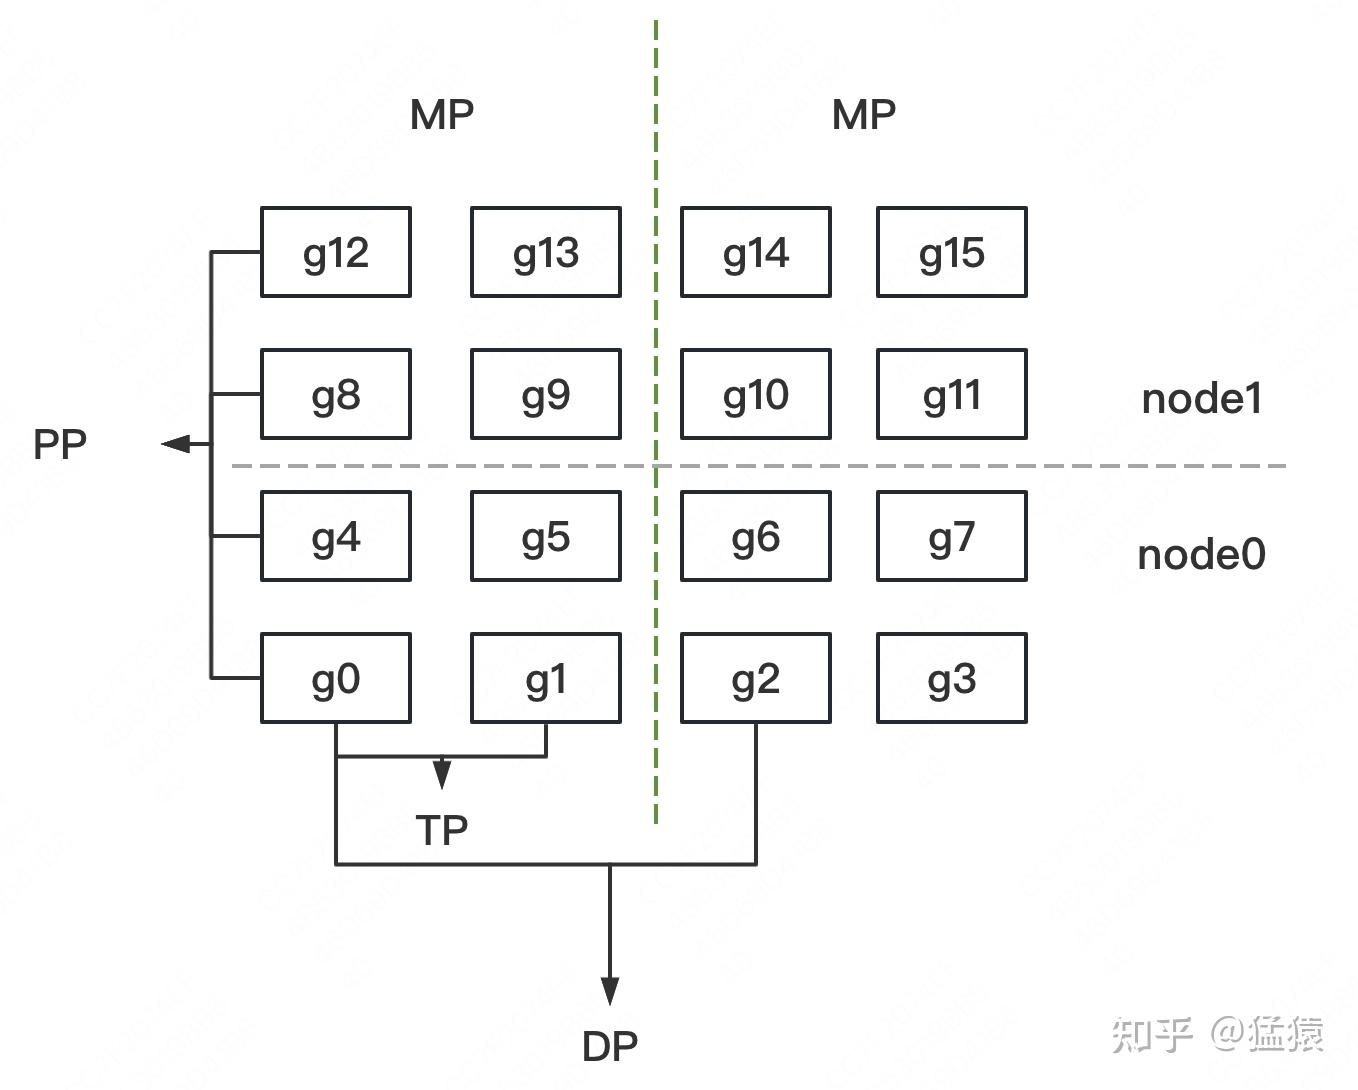
一个实例如下
-
示例的分组
- MP:模型并行组(Model Parallism)。假设一个完整的模型需要布在 8 块 GPU 上,则如图所示,我们共布了 2 个 model replica(2 个 MP)。MP 组为:
[[g0, g1, g4, g5, g8, g9, g12, g13], [g2, g3, g6, g7, g10, g11, g14, g15]] - TP:张量并行组(Tensor Parallism)。对于一个模型的每一层,我们将其参数纵向切开,分别置于不同的 GPU 上,则图中一共有 8 个 TP 组。TP 组为:
[[g0, g1], [g4, g5],[g8, g9], [g12, g13], [g2, g3], [g6, g7], [g10, g11], [g14, g15]] - PP:流水线并行组(Pipeline Parallism)。对于一个模型,我们将其每一层都放置于不同的 GPU 上,则图中一共有 4 个 PP 组。PP 组为:
[[g0, g4, g8, g12], [g1, g5, g9, g13], [g2, g6, g10, g14], [g3, g7, g11, g15]] - DP:数据并行组(Data Parallism)。经过上述切割,对维护有相同模型部分的 GPU,我们就可以做数据并行,则图中共有 8 个 DP 组。DP 组为
[[g0, g2], [g1, g3], [g4, g6], [g5, g7], [g8, g10], [g9, g11], [g12, g14], [g13, g15]]
- MP:模型并行组(Model Parallism)。假设一个完整的模型需要布在 8 块 GPU 上,则如图所示,我们共布了 2 个 model replica(2 个 MP)。MP 组为:
-
分组的原则
- MP 设定原则:MP 其实由 TP+PP 共同决定;在开始训练前,需要我们根据实际模型,预估训练时显存消耗(特别注意峰值显存),来为模型安排 GPU 资源
- TP、DP 和 PP 设定原则
- 一般而言,通讯量 TP>DP>PP
- 通讯量大的尽量放入一台机器内,因为机器内带宽高
- 所以在图例中,TP 和 DP 不跨机,PP 跨机
- 在使用 Megatron 时,很多项目不使用 PP,而仅用 TP+DP ,此时一般将 TP 放入一台机器内,令 DP 跨机(比如 codegeex)
-
分组的目的
- 分配进程
- 确认分组方案后,在每块 GPU 上启动一个进程(process),每个进程独立执行自己所维护的那部分模型的计算,实现并行训练
- 进程 0~15,为一个进程大组(group),其下的每一个 DP/MP/PP 组,为一个进程子组(subgroup)
- 组间通讯
- 确认 DP/TP/PP 组,并分配好进程后,就能进一步设置不同进程间的通讯方案
- 例如属于一个 DP 组的 g0 和 g2 需要进行梯度通讯,属于一个 PP 组的 g4 和 g8 需要进行层间输出结果的通讯
- 分配进程
-
代码实现
def _initialize_distributed(): """Initialize torch.distributed and mpu. | Node1 | Node2 | ____________| p1 | p2 | p3 | p4 | local_rank | 0 | 1 | 0 | 1 | rank | 0 | 1 | 2 | 3 | node: 物理结点,1台机器或者1个容器,图中2个物理结点 rank:进程在全局上的序号,图中4个进程 local_rank:进程在 node 上的序号 torch.cuda.device_count():当前进程所在的 node 上可使用的 GPU 的数量 device:GPU 在某个 node 上的编号 该函数作用: 1、设置分布式环境:初始化进程,分配GPU,并设置进程大组(group) 2、制定DP/TP/PP分组策略,设置进程子组(subgroup) 3、设置DeepSpeed ZeRO-R,对activation进行优化 """ args = get_args() device_count = torch.cuda.device_count() # 当前进程所在的node上可使用的GPU的数量 if torch.distributed.is_initialized(): # 如果已创建好分布式环境 if args.rank == 0: # 在0号进程上打印出“创建完毕”的日志 print( "torch distributed is already initialized, " "skipping initialization ...", flush=True, ) args.rank = torch.distributed.get_rank() # 取得当前进程的全局序号 args.world_size = torch.distributed.get_world_size() # 取得全局进程的个数 else: # 如果未创建好分布式环境 if args.rank == 0: print("> initializing torch distributed ...", flush=True) # 1. 初始化进程,分配GPU,并设置进程大组(group) if device_count > 0: device = args.rank % device_count # 1块进程1个GPU,device为GPU编号;例如图例中的进程9,其所在机器上有8块卡,因此进程9使用的gpu编号为8%9=1 if args.local_rank is not None: assert ( args.local_rank == device ), "expected local-rank to be the same as rank % device-count." else: args.local_rank = device if args.force_device is not None: print( f" > forcefully set the device to {args.force_device}, originally {device}" ) device = args.force_device torch.cuda.set_device(device) # 为当前进程分配GPU # 设置进程大组 init_method = "tcp://" master_ip = os.getenv("MASTER_ADDR", "localhost") # 获取rank=0进程的ip master_port = os.getenv("MASTER_PORT", "6000") # 获取rank=0进程的端口 init_method += master_ip + ":" + master_port print( f" > (rank={args.rank}) initializing process group: " f"world_size={args.world_size} " f"backend={args.distributed_backend} " f"init_method={init_method}", flush=True, ) timeout = datetime.timedelta(minutes=args.dist_timeout) torch.distributed.init_process_group( backend=args.distributed_backend, world_size=args.world_size, rank=args.rank, init_method=init_method, timeout=timeout ) print(f" > (rank={args.rank}) process group initialized") # 2、制定DP/TP/PP分组策略,设置进程子组(subgroup) if device_count > 0: if mpu.model_parallel_is_initialized(): print("model parallel is already initialized") else: mpu.initialize_model_parallel( # megatron/mpu/initialize.py args.tensor_model_parallel_size, args.pipeline_model_parallel_size, args.virtual_pipeline_model_parallel_size, ) # 设置DeepSpeed ZeRO-R,对activation进行优化 if args.deepspeed and args.deepspeed_activation_checkpointing: setup_deepspeed_random_and_activation_checkpointing(args) -
初始化分组策略
def initialize_model_parallel( tensor_model_parallel_size_=1, pipeline_model_parallel_size_=1, virtual_pipeline_model_parallel_size_=None, ): """ Initialize model data parallel groups. Arguments: tensor_model_parallel_size: number of GPUs used to parallelize model tensor. pipeline_model_parallel_size: number of GPUs used to parallelize model pipeline. Let's say we have a total of 16 GPUs denoted by g0 ... g15 and we use 2 GPUs to parallelize the model tensor, and 4 GPUs to parallelize the model pipeline. The present function will create 8 tensor model-parallel groups, 4 pipeline model-parallel groups and 8 data-parallel groups as: 8 data_parallel groups: [g0, g2], [g1, g3], [g4, g6], [g5, g7], [g8, g10], [g9, g11], [g12, g14], [g13, g15] 8 tensor model-parallel groups: [g0, g1], [g2, g3], [g4, g5], [g6, g7], [g8, g9], [g10, g11], [g12, g13], [g14, g15] 4 pipeline model-parallel groups: [g0, g4, g8, g12], [g1, g5, g9, g13], [g2, g6, g10, g14], [g3, g7, g11, g15] 2 model-parallel group: [g0, g1, g4, g5, g8, g9, g12, g13], [g2, g3, g6, g7, g10, g8, g14, g15] Note that for efficiency, the caller should make sure adjacent ranks are on the same DGX box. For example if we are using 2 DGX-1 boxes with a total of 16 GPUs, rank 0 to 7 belong to the first box and ranks 8 to 15 belong to the second box. """ if torch.distributed.get_rank() == 0: print( "> initializing tensor model parallel with size {}".format( tensor_model_parallel_size_ ) ) print( # 打印出流水线模型并行的度 "> initializing pipeline model parallel with size {}".format( pipeline_model_parallel_size_ ) ) # Get world size and rank. Ensure some consistencies. assert torch.distributed.is_initialized() # 确保torch已经做了分布式初始化 world_size = torch.distributed.get_world_size() # 得到全局进程的总数 tensor_model_parallel_size = min(tensor_model_parallel_size_, world_size) pipeline_model_parallel_size = min(pipeline_model_parallel_size_, world_size) ensure_divisibility( # 后者表示一个完整模型所占的gpu数,我们要保证前者能被后者整除 world_size, tensor_model_parallel_size * pipeline_model_parallel_size ) # 在codegeex中,TP_size=8, PP_size=1,world_size = 1536,因此DP_size是1536/(8*1) = 192 data_parallel_size = world_size // ( # 根据TP_size和PP_size,求出DP_size tensor_model_parallel_size * pipeline_model_parallel_size ) num_tensor_model_parallel_groups = world_size // tensor_model_parallel_size # TP的组数 num_pipeline_model_parallel_groups = world_size // pipeline_model_parallel_size # PP的组数 num_data_parallel_groups = world_size // data_parallel_size # DP的组数 if virtual_pipeline_model_parallel_size_ is not None: global _VIRTUAL_PIPELINE_MODEL_PARALLEL_RANK global _VIRTUAL_PIPELINE_MODEL_PARALLEL_WORLD_SIZE _VIRTUAL_PIPELINE_MODEL_PARALLEL_RANK = 0 _VIRTUAL_PIPELINE_MODEL_PARALLEL_WORLD_SIZE = ( virtual_pipeline_model_parallel_size_ ) rank = torch.distributed.get_rank() # 获取当前进程的全局rank # Build the data-parallel groups.(设置DP组) global _DATA_PARALLEL_GROUP # 保存DP组,如[[0,2], [1,3]...],数字表示进进程的全局序号 assert _DATA_PARALLEL_GROUP is None, "data parallel group is already initialized" all_data_parallel_group_ranks = [] for i in range(pipeline_model_parallel_size): start_rank = i * num_pipeline_model_parallel_groups end_rank = (i + 1) * num_pipeline_model_parallel_groups for j in range(tensor_model_parallel_size): ranks = range(start_rank + j, end_rank, tensor_model_parallel_size) all_data_parallel_group_ranks.append(list(ranks)) group = torch.distributed.new_group(ranks) # 设置DP组 if rank in ranks: _DATA_PARALLEL_GROUP = group # Build the model-parallel groups.(设置MP组) global _MODEL_PARALLEL_GROUP # 保存MP组 assert _MODEL_PARALLEL_GROUP is None, "model parallel group is already initialized" for i in range(data_parallel_size): ranks = [ data_parallel_group_ranks[i] for data_parallel_group_ranks in all_data_parallel_group_ranks ] group = torch.distributed.new_group(ranks) # 设置MP组 if rank in ranks: _MODEL_PARALLEL_GROUP = group # Build the tensor model-parallel groups.(设置TP组) global _TENSOR_MODEL_PARALLEL_GROUP # 保存TP组 assert ( _TENSOR_MODEL_PARALLEL_GROUP is None ), "tensor model parallel group is already initialized" for i in range(num_tensor_model_parallel_groups): ranks = range( i * tensor_model_parallel_size, (i + 1) * tensor_model_parallel_size ) group = torch.distributed.new_group(ranks) # 设置TP组 if rank in ranks: _TENSOR_MODEL_PARALLEL_GROUP = group # Build the pipeline model-parallel groups and embedding groups # (first and last rank in each pipeline model-parallel group).(设置PP组与embedding组) global _PIPELINE_MODEL_PARALLEL_GROUP # 设置PP组 global _PIPELINE_GLOBAL_RANKS assert ( _PIPELINE_MODEL_PARALLEL_GROUP is None ), "pipeline model parallel group is already initialized" global _EMBEDDING_GROUP assert _EMBEDDING_GROUP is None, "embedding group is already initialized" for i in range(num_pipeline_model_parallel_groups): ranks = range(i, world_size, num_pipeline_model_parallel_groups) group = torch.distributed.new_group(ranks) # 设置PP组 if rank in ranks: _PIPELINE_MODEL_PARALLEL_GROUP = group _PIPELINE_GLOBAL_RANKS = ranks # Setup embedding group (to exchange gradients between # first and last stages). if len(ranks) > 1: embedding_ranks = [ranks[0], ranks[-1]] else: embedding_ranks = ranks group = torch.distributed.new_group(embedding_ranks) # 设置embedding组 if rank in embedding_ranks: _EMBEDDING_GROUP = group -
总的来说,使用
torch.distributed.new_group(ranks)在进程大组下设置子组 -
ranks 是 list of list,表示对进程序号的划分,例如设置 DP 组,则 ranks 为
[[0,2], [1,3]...],以此类推 -
将划分结果存在全局变量中(例如
_DATA_PARALLEL_GROUP),方便在后续切割模型时使用 -
同时,定义以下函数,使得对于任意一个进程,都能查到它在 DP/TP/PP 组中的局部序号(local_rank),以及它对应的 DP/TP/PP 组的 world_size,这也是为后续切割模型使用
def get_tensor_model_parallel_group(): """Get the tensor model parallel group the caller rank belongs to.""" assert ( _TENSOR_MODEL_PARALLEL_GROUP is not None ), "intra_layer_model parallel group is not initialized" return _TENSOR_MODEL_PARALLEL_GROUP def set_tensor_model_parallel_world_size(world_size): """Set the tensor model parallel size""" global _MPU_TENSOR_MODEL_PARALLEL_WORLD_SIZE _MPU_TENSOR_MODEL_PARALLEL_WORLD_SIZE = world_size def get_tensor_model_parallel_rank(): """Return my rank for the tensor model parallel group. my_rank指的就是local_rank,例如[g2, g3]这一个TP组,rank为2,3;local_rank为0,1 """ global _MPU_TENSOR_MODEL_PARALLEL_RANK if _MPU_TENSOR_MODEL_PARALLEL_RANK is not None: return _MPU_TENSOR_MODEL_PARALLEL_RANK return torch.distributed.get_rank(group=get_tensor_model_parallel_group()) -
为什么还有一个 embedding_group?
- 在 GPT 类模型中,输入层和输出层共享一个 word_embedding
- 因此,在计算完梯度,更新 embedding 权重前,输入和输出层需要进行通讯,保证 word_embedding 完全一致
- 也即 PP 组中的第一个和最后一个进程需要通讯
- 设置进程子组的目的就是进一步划分通讯组,因此这里再添加一个 embedding_group
-
DeepSpeed ZeRO-R
- 在实际应用中,通常采用 DeepSpeed-Megatron 的方式,借助微软 DeepSpeed 库,通过 ZeRO 技术,帮助我们更好节省显存
模型并行
-
在分布式训练中,是面向进程编程的,python 脚本处理的是发生在一个进程上的逻辑,因此需要根据进程 ID(可以是全局的,也可以是 DP/TP/PP 组内的)来处理不同的逻辑
-
模型切割的方式
- 先定义出完整的模型,并对模型参数初始化,然后根据进程 ID 取出相应子模型,搬运到 GPU 上
- 直接根据进程 ID,设计好当前子模型,进行参数初始化,然后搬运到 GPU 上
-
在分布式训练中,随机种子决定了模型是否能够复现
-
例如在使用 activation checkpoint 节省显存时,在反向传播过程中就需要重新计算前向传播所得到的激活值,此时就必须完整复现之前前向传播的过程
-
在进行嵌入层的 TP 分割时,两块被分割的词向量表需要采用不同的随机种子,因为若采用相同的随机种子,则两块词向量表的结果完全意义,等价于先随机初始化词向量表然后再进行分割
-
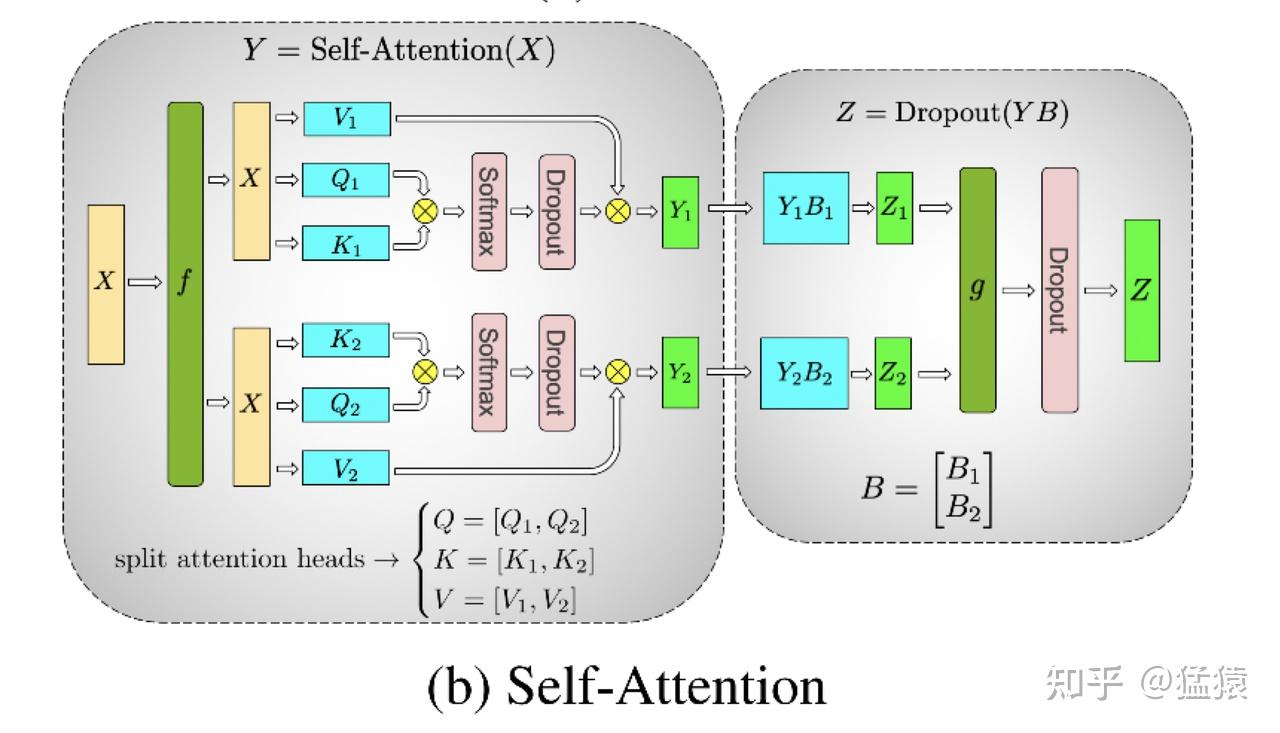
再例如下图中的 Dropout
- 左侧方框内的两个 dropout 层在初始化阶段需配置不同的随机种子。这是因为只有采用不同的随机种子,才能等价于先对完整的 dropout 层完成初始化,再按照实际计算需求对其进行切割处理,确保该环节的计算逻辑符合预期
- 右侧方框对应的 dropout 层(实际存在两个 dropout 层,分别部署在两块 GPU 上)在初始化时则需要使用相同的随机种子。原因在于此时两块 GPU 的输出已通过 AllReduce 操作实现完全一致,而完成 AllReduce 后两块 GPU 会继续独立执行后续计算,因此虽仅绘制一个 dropout 示意,但实际存在的两个 dropout 层需保证初始化种子相同,以维持计算的一致性
-
-
一般在 TP/PP 组内,需要设定不同的随机种子;而在 DP 组中,设定相同的随机种子
-
一般模型切割准备的代码如下
# 2、模型并行:定义模型架构,并切割模型(本文重点) model, optimizer, lr_scheduler = setup_model_and_optimizer(model_provider) -
其一般流程如下
- 定义模型架构并切割模型
get_model(model_provider) - 设置优化器
get_megatron_optimizer - 设置学习率
get_learning_rate_scheduler
- 定义模型架构并切割模型
-
get_model(model_provider)- 在 CPU 上定义模型,Pytorch 默认在 CPU 上定义模型 (nn.Module)
model_provider是一个函数,调用它即可返回 CPU 版的模型 - 将模型从 CPU 搬运至 GPU 上
- 借助 DeepSpeed 管理,利用其管理模型的分布式,DP 组间的显存优化
- 手动搬运管理
- 显存搬运:手动将模型搬运到当前进程所对应的 GPU 上
- 权重精度设定:在模型训练中,把权重精度从 fp32 降至 fp16,是一种节省显存的好办法;如果使用混合精度训练,需要将模型搬运到 GPU 上后,修改模型精度
- 初始化 DP 组:定义 DP 组间 forward、backward 和梯度计算与通讯等方法;TP/PP 组的这些方法是认为定义的并且在定义 CPU 模型时就已经设计好;而 DP 组可以直接使用 DistributedDataParallel,并在此基础上添加对碎片化内存的管理、对计算梯度时的精度控制
- 在 CPU 上定义模型,Pytorch 默认在 CPU 上定义模型 (nn.Module)
-
代码实现
def get_model(model_provider_func): """Build the model.""" args = get_args() # 1、定义并构建CPU版模型 if ( # 1.1、当分布式进行框架采用virtual pipeline (是NVDIA后续提出的对Megatron的优化方法,可先忽略不看) mpu.get_pipeline_model_parallel_world_size() > 1 and args.virtual_pipeline_model_parallel_size is not None ): model = [] for i in range(args.virtual_pipeline_model_parallel_size): mpu.set_virtual_pipeline_model_parallel_rank(i) # Set pre_process and post_process only after virtual rank is set. pre_process = mpu.is_pipeline_first_stage() post_process = mpu.is_pipeline_last_stage() this_model = model_provider_func( pre_process=pre_process, post_process=post_process ) model.append(this_model) else: # 1.2 其余情况 # 判断当前进程是否是PP组的第一个进程(例如第一部分图例中PP组的g0) pre_process = mpu.is_pipeline_first_stage() # 判断当前进程是否是PP组的最后一个进程(例如第一部分图例中PP组的g12) post_process = mpu.is_pipeline_last_stage() # 构建CPU版CodeGeeX模型 model = model_provider_func(pre_process=pre_process, post_process=post_process) ... # 2、将模型从CPU搬运到GPU上 # 2.1 如果采用Megatron-DeepSpeed的方式,则直接返回模型,后面的搬运,数据并行等工作将由deepspeed来完成 # ref:https://www.deepspeed.ai/tutorials/megatron/ if args.deepspeed: return model # 将当前进程所维护的模型,从CPU搬运到GPU上(GPU即为在初始化时为当前进程分配的那块GPU) print(f" > moving model to GPU ...", flush=True) for model_module in model: model_module.cuda(torch.cuda.current_device()) print(f" > moving to GPU done", flush=True) # fp16转换(pytorch默认模型参数精度为fp32,依需决定计算过程中是否要转成fp16,节省显存) if args.fp16 or args.bf16: print(f" > converting model to fp16 ...", flush=True) model = [Float16Module(model_module, args) for model_module in model] print(f" > converting to fp16 done", flush=True) # 采用pytorch定义的DistributedDataParallel管理数据并行 if args.DDP_impl == "torch": i = torch.cuda.current_device() model = [ torchDDP( model_module, device_ids=[i], output_device=i, process_group=mpu.get_data_parallel_group(), # 数据并行的组 ) for model_module in model ] return model # 采用自定义的DistributedDataParallel管理数据并行 # 即在pytorch的DistributedDataParallel的基础上,自己再定义内存管理、梯度精度等计算方式,更有效利用显存 if args.DDP_impl == "local": # 自定义的数据并行类在megatron/model/distributed.py下 print(f" > creating DDP model ...", flush=True) model = [ LocalDDP( model_module, args.accumulate_allreduce_grads_in_fp32, args.use_contiguous_buffers_in_ddp, ) for model_module in model ] print(f" > creating DDP model done", flush=True) return model raise NotImplementedError( "Unknown DDP implementation specified: {}. " "Exiting.".format(args.DDP_impl) ) -
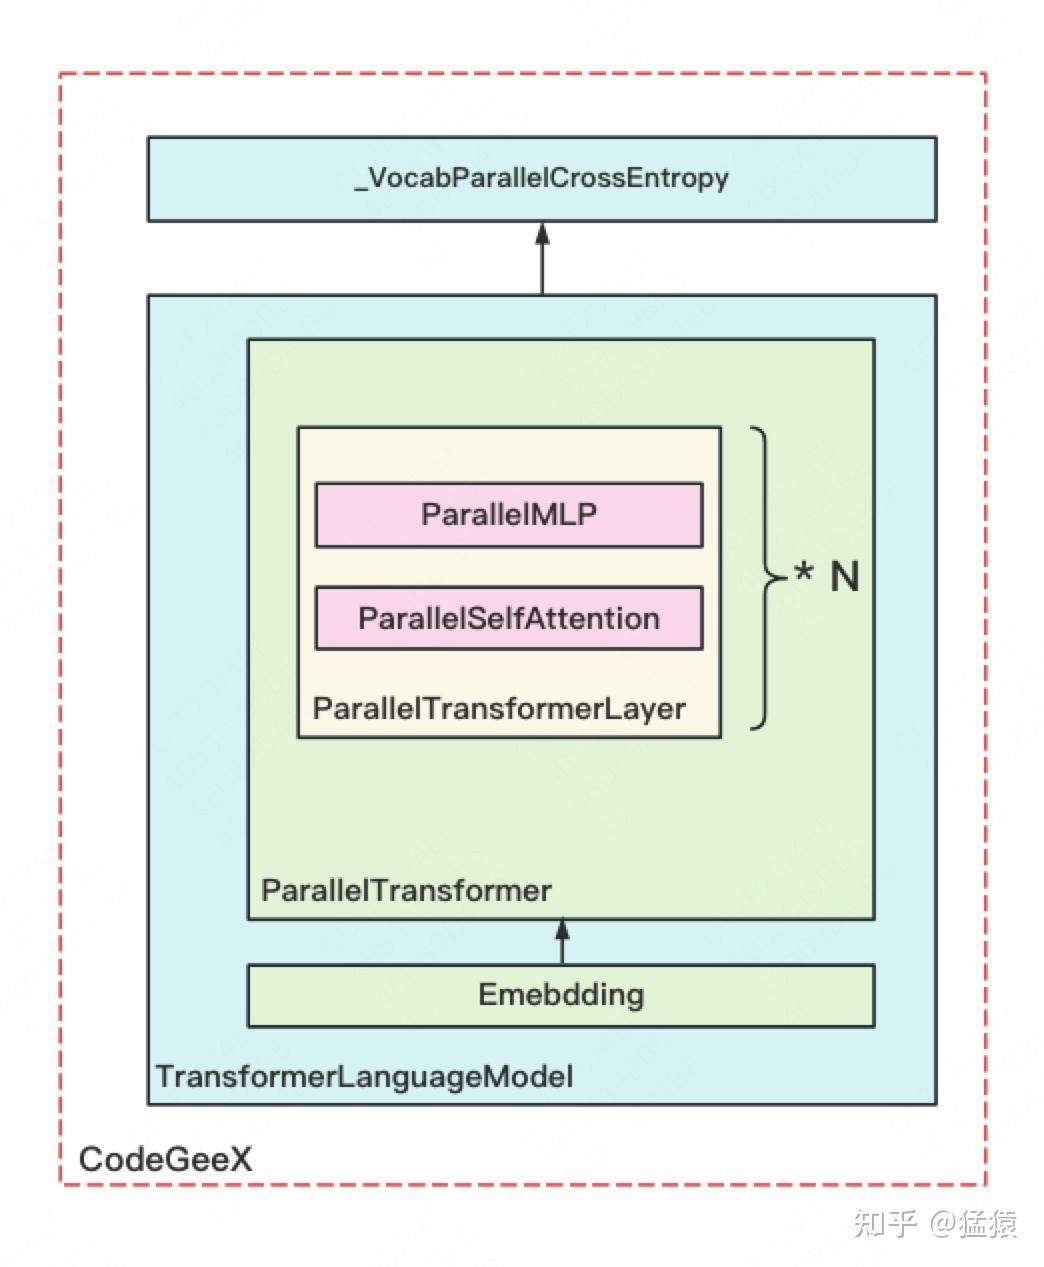
CodeGeeX 的模型定义
-
模型结构
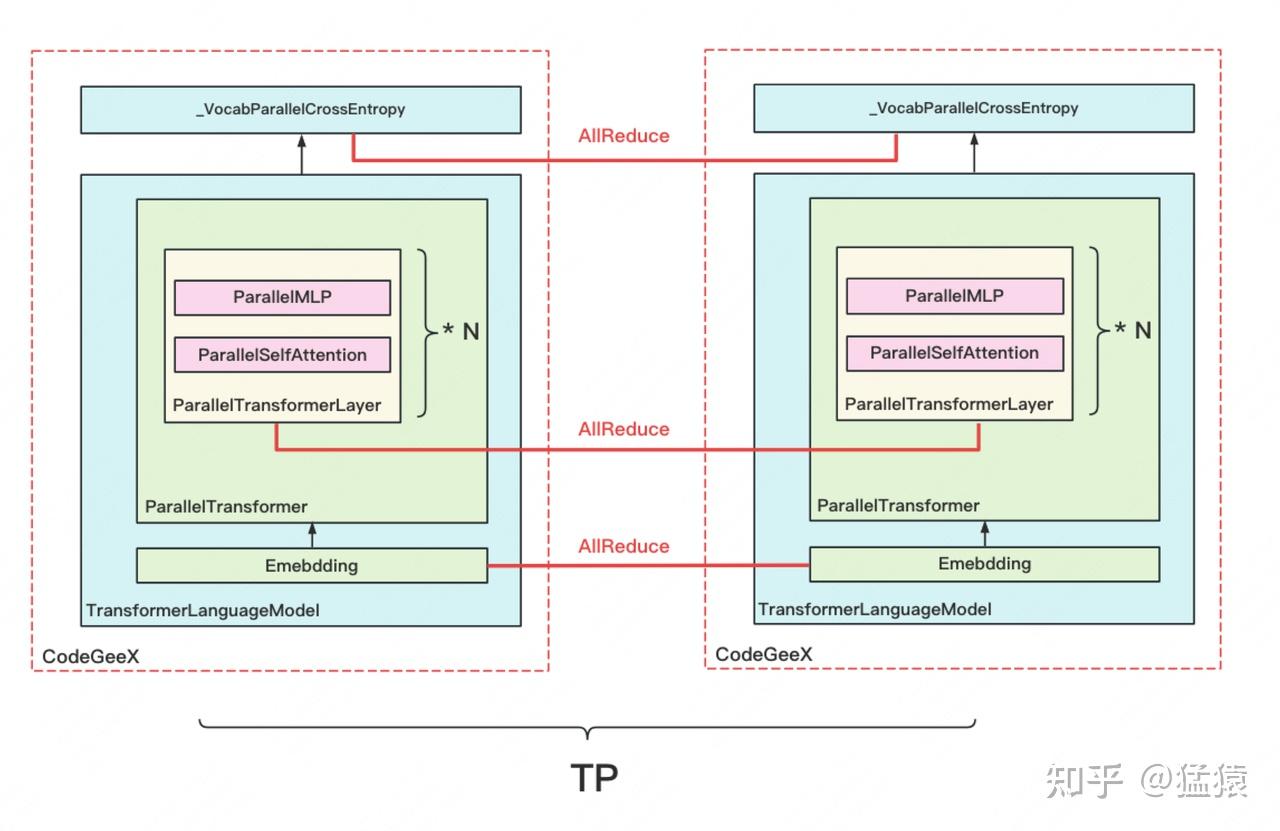
CodeGeeX: 定义一块 GPU 上的模型,它由TransformerLanguageModel和_VocabParallelCrossEntropy这两个核心类组成TransformerLanguageModel:定义每块 GPU 上输入层 embedding 和中间 block 层的结构Embedding: 定义每块 GPU 上输入层 embedding 结构及相关计算,输出结果已 AllReduce(TP 组间)ParallelTransformer:定义每块 GPU 上所有中间 blocks 的结构及相关计算,输出结果已 AllReduce(TP 组间)ParallelTransformerLayer: 定义每块 GPU 上单个 block 的结构及相关计算,输出结果已 AllReduce(TP 组间)ParallelSelfAttention: 定义每块 GPU 上单个 block 中,attention 的结构及相关计算,输出结果已 AllReduce(TP 组间)ParallelMLP: 定义每块 GPU 上单个 block 中,mlp 层的结构及相关计算,输出结果已 AllReduce(TP 组间)_VocabParallelCrossEntropy: torch.autograd.Function,定义每块 GPU 上,输出层 embedding、softmax 和 loss 等结构及相关计算
-
这里对于模型的每一层输出,都需要在 TP 组间进行 all-reduce,来保证下一层拿到的输入也是完整的
MegatronModule
-
上述所涉及的类,均不是直接继承自
nn.Module,而是皆继承于自定义的class MegatronModule(torch.nn.Module) -
这个类的主要作用,是令 PP 组的第一个进程和最后一个进程满足输入和输出共用一个词嵌入表
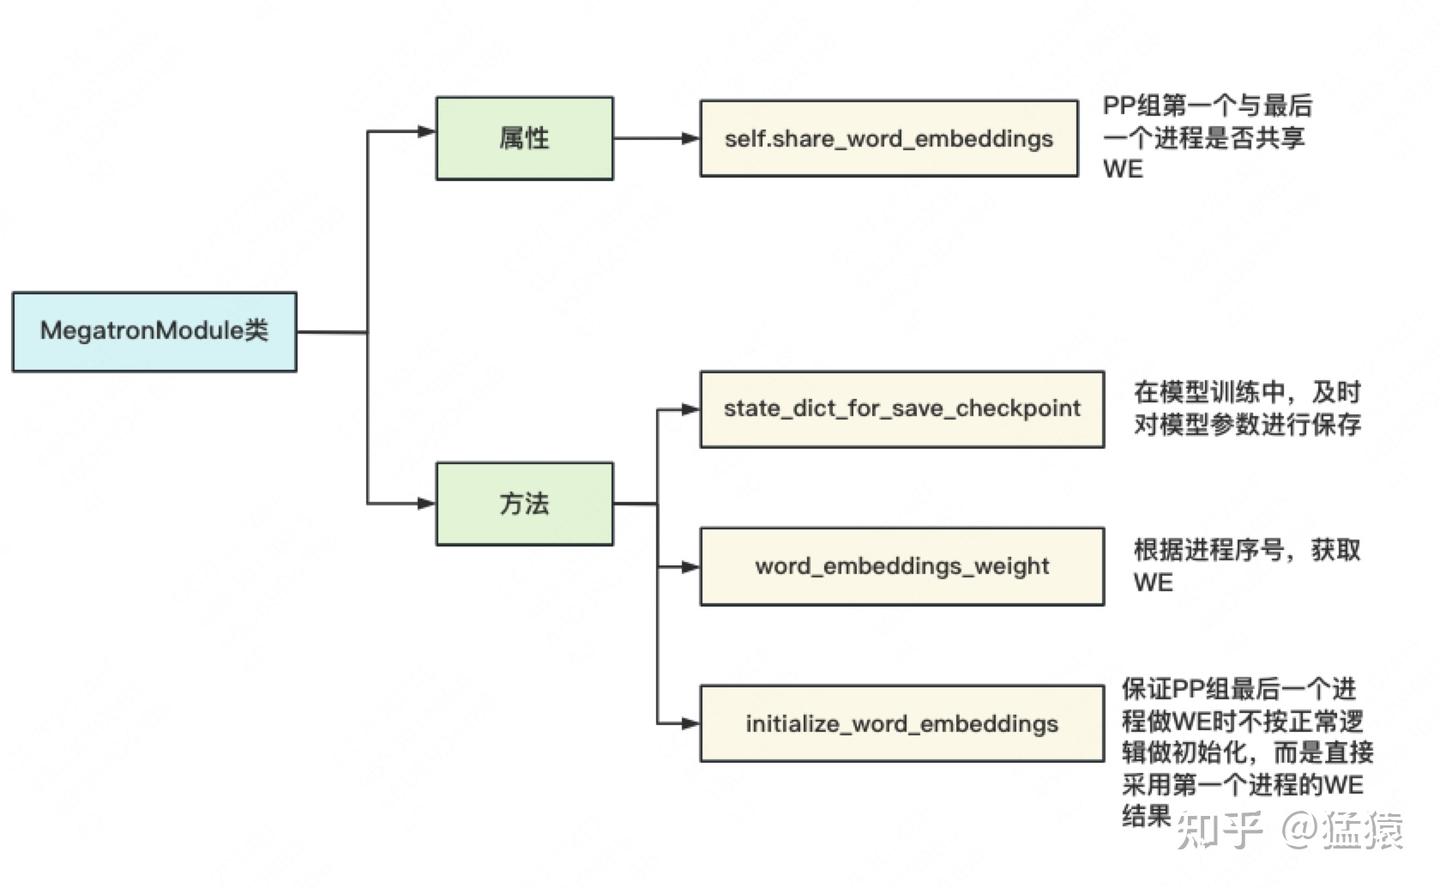
-
代码如下
class MegatronModule(torch.nn.Module):
    """Megatron specific extensions of torch Module with support
    for pipelining."""

    def __init__(self, share_word_embeddings=True):
        super(MegatronModule, self).__init__()
        # input和output是否要共享一套WE
        self.share_word_embeddings = share_word_embeddings

    def state_dict_for_save_checkpoint(
        self, destination=None, prefix="", keep_vars=False
    ):
        """Use this function to override the state dict for
        saving checkpoints."""
        # 模型训练中,及时将参数保存到指定位置(设置checkpoint),
        # 这样在训练出问题时,可以从checkpoint点重新load参数,继续训练
        return self.state_dict(destination, prefix, keep_vars)

    def word_embeddings_weight(self):
        """获取word_embedding"""
        if mpu.is_pipeline_first_stage(ignore_virtual=True):
            return self.language_model.embedding.word_embeddings.weight
        if mpu.is_pipeline_last_stage(ignore_virtual=True):
            if not self.share_word_embeddings:
                raise Exception( # 强制要求共享一套embedding
                    "word_embeddings_weight() called for last "
                    "stage, but share_word_embeddings is false"
                )
            return self.word_embeddings.weight # 参见initialize_word_embeddings中WE的定义
        raise Exception( # 如果当前进程是PP组的中间进程,则其上未维护WE,因此当然获取不到
            "word_embeddings_weight() should be " "called for first and last stage only"
        )

    def initialize_word_embeddings(self, init_method_normal):
        """强制PP组最后一个进程初始化WE时,直接使用PP组第一个进程的WE"""
        args = get_args()
        if not self.share_word_embeddings: # 强制share embeddingg
            raise Exception(
                "initialize_word_embeddings() was called but "
                "share_word_embeddings is false"
            )

        # PP组并行度为1时,第一层和最后一层都在一块GPU上,天然共享WE,无需做强制
        if args.pipeline_model_parallel_size == 1:
            return

        # ---------------------------------------------------
        # 如果流水线并行的度不为1时,依次做三件事:
        # 【初始化时】:
        # 1、在PP组最后一个进程上初始化一个WE,令其取值全为0
        # 2、在PP组第一个进程与最后一个进程间做一次AllReduce,保证两者的WE完全一致
        # 【训练时】:
        # 3、每次想在PP组第一个/最后一个进程上使用WE时,要做一次通信,保证两者用的WE完全一致

        if mpu.is_pipeline_last_stage(): # 若当前进程是PP组最后一个进程
            assert not mpu.is_pipeline_first_stage()
            self._word_embeddings_for_head_key = "word_embeddings_for_head"
            # 初始化一个WE(已按vocab_size维度切割,可参见Megatron原理篇对WE的讲解)
            # VocabParallelEmbedding将在下文详细讲解
            self.word_embeddings = mpu.VocabParallelEmbedding(
                args.padded_vocab_size, # vocab_size
                args.hidden_size, # embed_dim
                init_method=init_method_normal(args.init_method_std), # 初始化方法(在model/utils.py下)
            )
            # 用0填充WE(等待下面做AllReduce后取得第一个进程上的WE)
            self.word_embeddings.weight.data.fill_(0)
            self.word_embeddings.weight.shared = True

        if torch.distributed.is_initialized():
            if mpu.is_pipeline_first_stage() or mpu.is_pipeline_last_stage(): # 若当前进程是PP组第一个或最后一个进程
                # 在两进程间做AllReduce,保证它们使用的WE完全一致
                # mpu.get_embedding_group:在源码解读1中讲过,是除DP/TP/PP之外设置的又一进程组,
                # 主要就是用来做关于WE的通讯
                torch.distributed.all_reduce(
                    self.word_embeddings_weight().data, group=mpu.get_embedding_group()
                )
        else:
            print(
                "WARNING! Distributed processes aren't initialized, so "
                "word embeddings in the last layer are not initialized. "
                "If you are just manipulating a model this is fine, but "
                "this needs to be handled manually. If you are training "
                "something is definitely wrong."
            )
Embedding
-
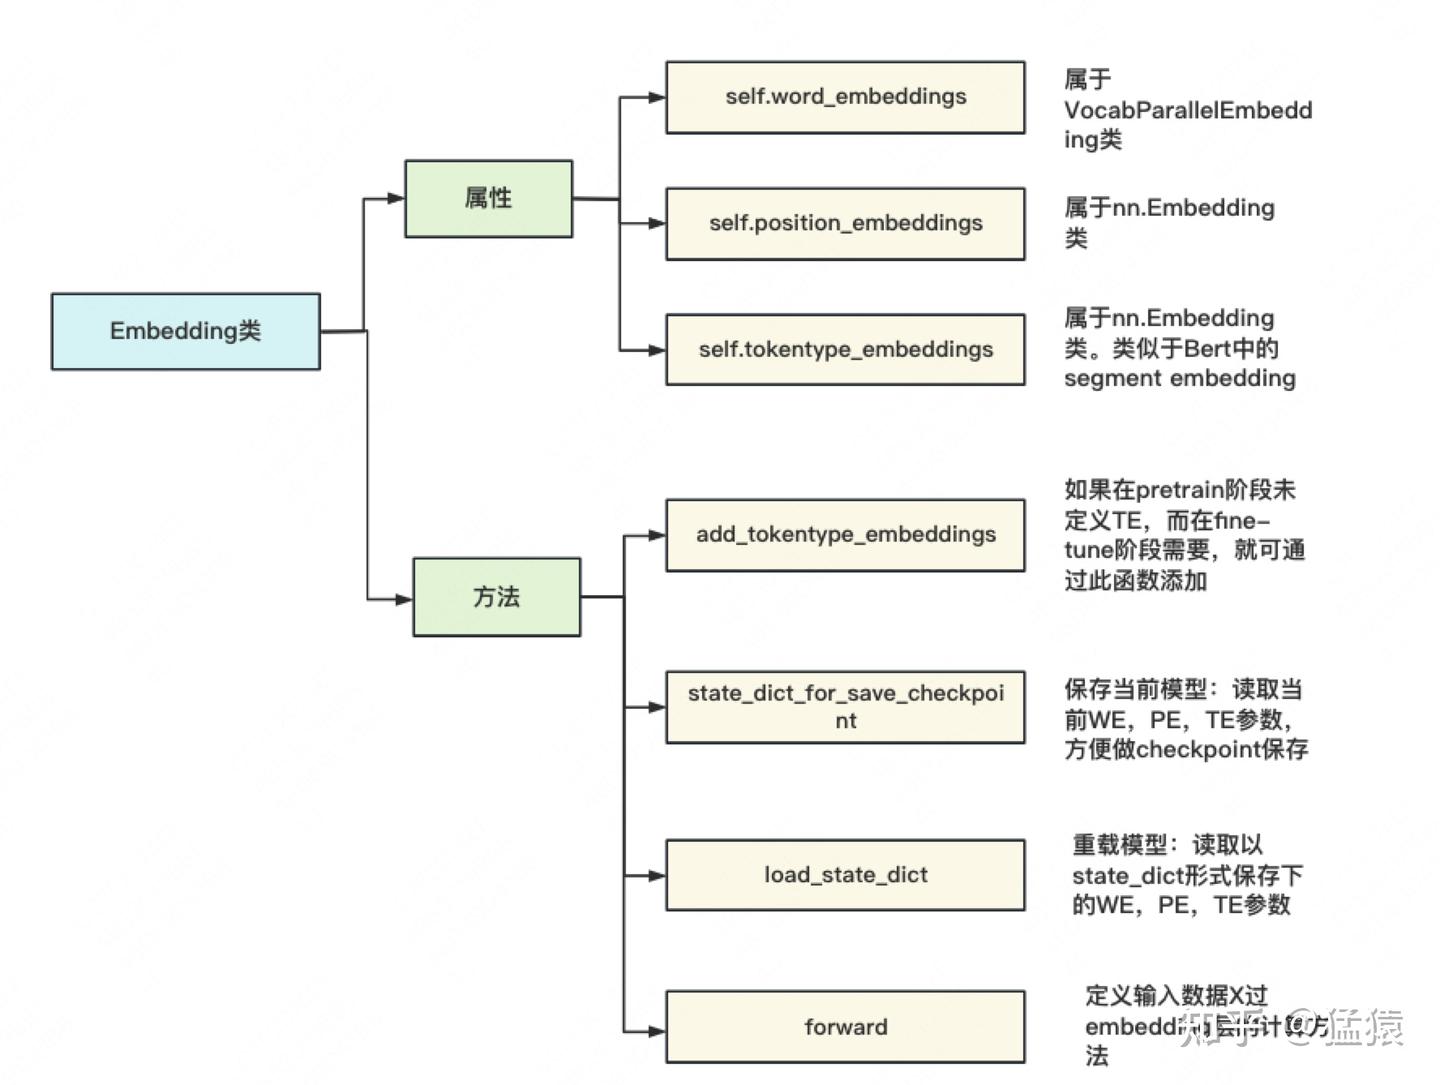
Embedding 类定义了 word/position/segment embedding,并定义输入 X 经过 embedding 层的计算方法
-
self.word_embeddings:来自自定义的VocabParallelEmbedding, 含 “Parallel” 则意味着参数在 TP 组间做了切割,因此self.word_embeddings是切割后的 WE -
self.position_embeddings和self.tokentype_embeddings这两者都和输入 X 相关,而输入 X 是不做切割的,因此这两者也无需切割 -
代码实现
class Embedding(MegatronModule):
    """Language model embeddings.

    Arguments:
        hidden_size: hidden size
        vocab_size: vocabulary size
        max_sequence_length: maximum size of sequence. This
                             is used for positional embedding
        embedding_dropout_prob: dropout probability for embeddings
        init_method: weight initialization method
        num_tokentypes: size of the token-type embeddings. 0 value
                        will ignore this embedding
    """

    def __init__(
        self,
        hidden_size, # 每个token的向量维度
        vocab_size, # 词表大小
        max_sequence_length, # 最长序列长度
        embedding_dropout_prob, # dropout probability for embeddings
        init_method, # 初始化权重的方法
        num_tokentypes=0, # 类似于Bert中的segment type
    ):
        super(Embedding, self).__init__()

        args = get_args()

        self.hidden_size = hidden_size
        self.init_method = init_method
        self.num_tokentypes = num_tokentypes
        self.max_sequence_length = max_sequence_length

        # WE size: (vocab_size//TP_N, hidden_size)
        # TP_N表示TP组模型并行度
        self.word_embeddings = mpu.VocabParallelEmbedding(
            vocab_size, self.hidden_size, init_method=self.init_method)
        self._word_embeddings_key = 'word_embeddings'

        self.vocab_size = vocab_size

        # PE size: (max_seq_len, hidden_size)
        self.position_embeddings = torch.nn.Embedding(
            max_sequence_length, self.hidden_size)
        self.position_embeddings = self.position_embeddings.half()
        self._position_embeddings_key = 'position_embeddings'
        # Initialize the position embeddings.
        self.init_method(self.position_embeddings.weight)

        # TE_size:(num_tokentypes, hidden_size)
        # TE类似于Bert中的segment embedding
        self._tokentype_embeddings_key = 'tokentype_embeddings'
        if self.num_tokentypes > 0:
            self.tokentype_embeddings = torch.nn.Embedding(self.num_tokentypes,
                                                           self.hidden_size)
            # Initialize the token-type embeddings.
            self.init_method(self.tokentype_embeddings.weight)
        else:
            self.tokentype_embeddings = None

        # Embeddings dropout
        self.embedding_dropout = torch.nn.Dropout(embedding_dropout_prob)

    def add_tokentype_embeddings(self, num_tokentypes):
        """如果在pretrain阶段未定义TE,而在fine-tune阶段TE,则可通过此函数添加
        """
        if self.tokentype_embeddings is not None:
            raise Exception('tokentype embeddings is already initialized')
        if torch.distributed.get_rank() == 0:
            print('adding embedding for {} tokentypes'.format(num_tokentypes),
                  flush=True)
        self.num_tokentypes = num_tokentypes
        self.tokentype_embeddings = torch.nn.Embedding(num_tokentypes,
                                                       self.hidden_size)
        # Initialize the token-type embeddings.
        self.init_method(self.tokentype_embeddings.weight)

    def forward(self, input_ids, position_ids, tokentype_ids=None):
        """定义输入X过embedding层的计算方法
        """

        # words_embeddings size = (b, seq_len, hidden_size)
        # 再次注意:self.word_embeddings做forward时,最终的输出结果是AllReduce的
        words_embeddings = self.word_embeddings(input_ids)
        # position_embeddings size = (b, seq_len, hidden_size)
        position_embeddings = self.position_embeddings(position_ids)
        # embedding = WE + PE
        # embedding size = (b, seq_len, hidden_size)
        embeddings = words_embeddings + position_embeddings
        # 依需要决定是否增加TE
        if tokentype_ids is not None:
            assert self.tokentype_embeddings is not None
            embeddings = embeddings + self.tokentype_embeddings(tokentype_ids)
        else:
            assert self.tokentype_embeddings is None

        # Dropout.
        embeddings = self.embedding_dropout(embeddings)

        return embeddings

    def state_dict_for_save_checkpoint(
        self, destination=None, prefix='', keep_vars=False,
    ):
        """For easy load.
        在模型训练过程中及时读取当前参数,方便及时保存(做checkpoint)
        篇幅限制,这里不展示细节
        """
        ...

    def load_state_dict(self, state_dict, strict=True):
        """Customized load.
        用于模型的重载。例如训到一半挂掉了,我们就重新初始化一个新模型,
        重载上个checkpoint保存下的权重。
        篇幅限制,这里不展示细节
        """
        ...
VocabParallelEmbedding
-
VocabParallelEmbedding 用于定义分布式的 word embedding

-
代码实现
class VocabParallelEmbedding(torch.nn.Module):
    """Embedding parallelized in the vocabulary dimension.

    This is mainly adapted from torch.nn.Embedding and all the default
    values are kept.
    Arguments:
        num_embeddings: vocabulary size.
        embedding_dim: size of hidden state.
        init_method: method to initialize weights.
    """

    def __init__(self, num_embeddings, embedding_dim, init_method=init.xavier_normal_):
        super(VocabParallelEmbedding, self).__init__()
        # Keep the input dimensions.
        self.num_embeddings = num_embeddings # vocab_size
        self.embedding_dim = embedding_dim # hidden_state.
        # Set the detauls for compatibility.
        self.padding_idx = None
        self.max_norm = None
        self.norm_type = 2.0
        self.scale_grad_by_freq = False
        self.sparse = False
        self._weight = None
        # 当前进程所在TP组进程总数
        self.tensor_model_parallel_size = get_tensor_model_parallel_world_size()
        # 根据当前进程在TP组中的序号,确定其所需维护的WE部分,沿着vocab维度对WE进行切割
        # 例如,进程id=0, 维护词表序号[0,5)范围内的数据;进程id=1,维护[5,10)
        (
            self.vocab_start_index,
            self.vocab_end_index,
        ) = VocabUtility.vocab_range_from_global_vocab_size(
            self.num_embeddings,
            get_tensor_model_parallel_rank(),
            self.tensor_model_parallel_size,
        )
        # 计算当前进程维护的词表大小
        self.num_embeddings_per_partition = (
            self.vocab_end_index - self.vocab_start_index
        )

        # 对WE做初始化
        args = get_args() # 读取预训练参数配置
        if args.use_cpu_initialization: # CPU上做初始化
            self.weight = Parameter( # 在CPU上先生成一个完整的WE
                torch.empty(
                    self.num_embeddings_per_partition,
                    self.embedding_dim,
                    dtype=args.params_dtype,
                    # dtype=torch.float32,
                )
            )
            # 对CPU上的WE做切割(随机种子在初始化分布式中已设定好,不用变)
            _initialize_affine_weight_cpu(
                self.weight,
                self.num_embeddings,
                self.embedding_dim,
                self.num_embeddings_per_partition,
                0,
                init_method, # 初始化权重的方法,例如xavier之类
            )
        else: # 在GPU上做初始化
            self.weight = Parameter( # 生成一个切割好的WE
                torch.empty(
                    self.num_embeddings_per_partition,
                    self.embedding_dim,
                    device=torch.cuda.current_device(),
                    dtype=args.params_dtype,
                    # dtype=torch.float32,
                )
            )
            # 在GPU上做初始化,注意TP组内不同进程采用不同的随机种子
            _initialize_affine_weight_gpu(
                self.weight, init_method, partition_dim=0, stride=1
            )

    def forward(self, input_):
        """定义输入X过WE的计算方法,输出结果已经过AllReduce"""
        if self.tensor_model_parallel_size > 1: # 如果使用TP
            # 如果在当前进程维护的WE上,找不到对应的单词,那么对应位置就赋0
            # 例如当前的数据的tokenid是:[2,7,1,5],当前维护的词表是[0,1,2](start_index=0, end_index = 3),
            # 则mask之后的数据为[2,0,1,0]
            # Build the mask.
            input_mask = (input_ < self.vocab_start_index) | (
                input_ >= self.vocab_end_index
            )
            # Mask the input.
            masked_input = input_.clone() - self.vocab_start_index
            masked_input[input_mask] = 0
        else:
            masked_input = input_

        # 输入X,过当前进程维护的部分WE的结果
        output_parallel = F.embedding(
            masked_input, # tensor containing indices into the embedding matrix
            self.weight, # 切割好的word embedding的权重
            self.padding_idx,
            self.max_norm,
            self.norm_type,
            self.scale_grad_by_freq,
            self.sparse,
        )
        # 当前词表不维护的部分,都设为0
        if self.tensor_model_parallel_size > 1:
            output_parallel[input_mask, :] = 0.0 #

        # 将TP组各GPU上的结果做AllReduce
        output = reduce_from_tensor_model_parallel_region(output_parallel)
        return output

def _initialize_affine_weight_cpu(...):
    """CPU版权重初始化。这个不难,大家可以自己阅读"""
    ...

def _initialize_affine_weight_gpu(...):
    """GPU版权重初始化。特别关注设置随机种子部分"""
    ...
    # 借助deepspeed或自定义的get_cuda_rng_tracker方法,对随机种子进行操作
    # get_cuda_rng_tracker细节,大家可自行阅读源码
    if ds_checkpointing.is_configured():
        global get_cuda_rng_tracker
        get_cuda_rng_tracker = ds_checkpointing.get_cuda_rng_tracker

    with get_cuda_rng_tracker().fork():
        init_method(weight)
ColumnParallelLinear
-
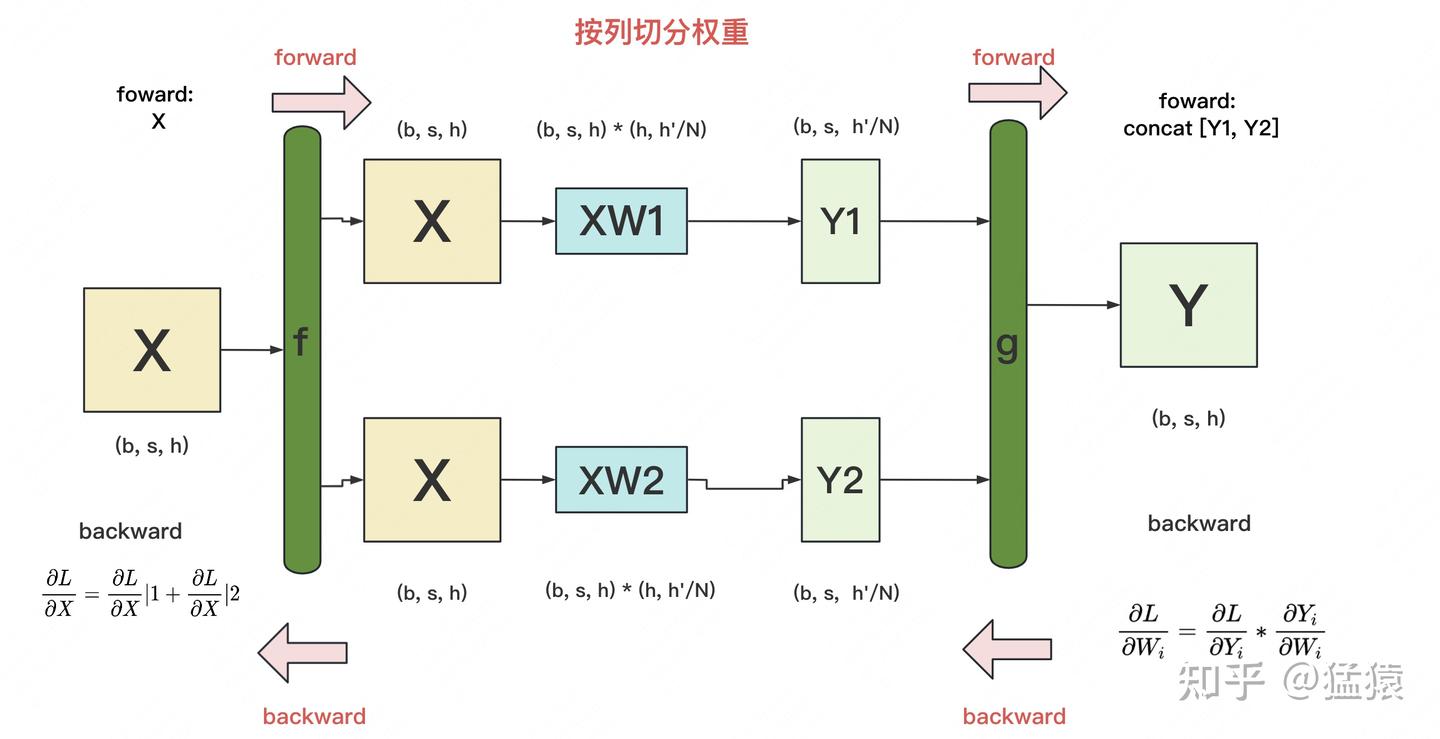
f 和 g 为一对共轭算子,可对应理解为两个 torch.autograd.Function 类,该类下可按需重写 forward 和 backward 方法:
-
f:对应代码中的 class _CopyToModelParallelRegion (torch.autograd.Function)
- forward 方法:直接复制输入数据;
- backward 方法:对梯度执行 AllReduce 操作
-
g:对应代码中的 class _GatherFromModelParallelRegion (torch.autograd.Function)
- forward 方法:对输出执行 all-gather 操作;
- backward 方法:对梯度执行 split 操作(每张卡经 all-gather 后已持有完整的 Y,以 Y 为起点计算梯度后,沿列维度 split 即可得到 Y1 和 Y2 的梯度)
-
代码实现
class ColumnParallelLinear(torch.nn.Module):
    """Linear layer with column parallelism.

    The linear layer is defined as Y = XA + b. A is parallelized along
    its second dimension as A = [A_1, ..., A_p].

    Arguments:
        input_size: first dimension of matrix A.
        output_size: second dimension of matrix A.
        bias: If true, add bias
        gather_output: If true, call all-gether on output and make Y avaiable
                       to all GPUs, otherwise, every GPU will have its output
                       which is Y_i = XA_i
        init_method: method to initialize weights. Note that bias is always set
                     to zero.
        stride: For the strided linear layers.
        keep_master_weight_for_test: This was added for testing and should be
                                     set to False. It returns the master weights
                                     used for initialization.
        skip_bias_add: This was added to enable performance optimations where bias
                       can be fused with other elementwise operations. we skip
                       adding bias but instead return it.
    """
    # 该类定义了切割后的权重W,例如对上图来说,W1和W2都可分别视为该类的一个实例

    def __init__(
        self,
        input_size, # W的第一个维度
        output_size, # W的第二个维度
        bias=True, # 是否需要引入bias
        gather_output=True, # 决定是否要将Y1和Y2做all-gather
        init_method=init.xavier_normal_,
        stride=1,
        keep_master_weight_for_test=False,
        skip_bias_add=False,
        params_dtype=None,
        skip_init=False,
        device=None,
    ):
        super(ColumnParallelLinear, self).__init__()

        # Keep input parameters
        self.input_size = input_size
        self.output_size = output_size
        self.gather_output = gather_output
        # Divide the weight matrix along the last dimension.
        # 当前进程所在TP组的总进程数
        world_size = get_tensor_model_parallel_world_size()
        # 每块GPU上维护的hidden_size的大小,等于 原hidden_zize // TP组总进程数
        self.output_size_per_partition = divide(output_size, world_size)
        self.skip_bias_add = skip_bias_add
        self.params_dtype = params_dtype
        self.device = device
        # Parameters.
        # Note: torch.nn.functional.linear performs XA^T + b and as a result
        # Initialize weight.
        args = get_args() # 取得命令行所有的参数
        if not skip_init:
            if args.use_cpu_initialization: # CPU上初始化
                self.weight = Parameter(
                    torch.empty(
                        self.output_size_per_partition,
                        self.input_size,
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )
                self.master_weight = _initialize_affine_weight_cpu( #
                    self.weight,
                    self.output_size,
                    self.input_size,
                    self.output_size_per_partition,
                    0,
                    init_method,
                    stride=stride,
                    return_master_weight=keep_master_weight_for_test,
                )
            else: # GPU上初始化
                self.weight = Parameter(
                    torch.empty(
                        self.output_size_per_partition,
                        self.input_size,
                        device=self.device if self.device is not None else torch.cuda.current_device(),
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )
                _initialize_affine_weight_gpu(
                    self.weight, init_method, partition_dim=0, stride=stride
                )
        else:
            self.register_parameter("weight", None)

        # 对bias做处理,道理同weight
        if bias and not skip_init:
            if args.use_cpu_initialization: # CPU上初始化
                self.bias = Parameter(
                    torch.empty(self.output_size_per_partition,
                                dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype)
                )
            else:
                self.bias = Parameter( # GPU上初始化
                    torch.empty(
                        self.output_size_per_partition,
                        device=self.device if self.device is not None else torch.cuda.current_device(),
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )

            set_tensor_model_parallel_attributes(self.bias, True, 0, stride)
            # Always initialize bias to zero.
            with torch.no_grad():
                self.bias.zero_()
        else:
            self.register_parameter("bias", None)

    def forward(self, input_):
        # 定义列切割中的f算子
        # 调用copy_to_tensor_model_parallel_region则新建一个_CopyToModelParallelRegion实例(见下)
        input_parallel = copy_to_tensor_model_parallel_region(input_)

        bias = self.bias if not self.skip_bias_add else None # 定义bias
        output_parallel = F.linear(input_parallel, self.weight, bias) # X * 切割好的权重
        # 决定是否要对每个进程上的输出结果做All-Reduce
        if self.gather_output:
            # 定义列切割中的g算子
            # 调用gather_from_tensor_model_parallel_region则新建一个_GatherFromModelParallelRegion实例(见下)
            output = gather_from_tensor_model_parallel_region(output_parallel) # 把各GPU上的输出按照列gather起来后,作为最终输出
        else:
            output = output_parallel # 否则最终输出还是自己算的那块GPU
        output_bias = self.bias if self.skip_bias_add else None
        return output, output_bias

# 列切割中的f与g
class _CopyToModelParallelRegion(torch.autograd.Function):
    """Pass the input to the model parallel region."""
    # 列切割下的f算子
    # forward:copy输入
    # backward:对梯度做AllReduce

    @staticmethod
    def symbolic(graph, input_):
        return input_

    @staticmethod
    def forward(ctx, input_):
        return input_

    @staticmethod
    def backward(ctx, grad_output):
        return _reduce(grad_output)

class _GatherFromModelParallelRegion(torch.autograd.Function):
    """Gather the input from model parallel region and concatinate."""
    # 列切割中的g算子
    # forward:All-Gather输出
    # backward:对梯度,沿着列方向做split

    @staticmethod
    def symbolic(graph, input_):
        return _gather(input_)

    @staticmethod
    def forward(ctx, input_):
        return _gather(input_)

    @staticmethod
    def backward(ctx, grad_output):
        return _split(grad_output)
RowParallelLinear
-
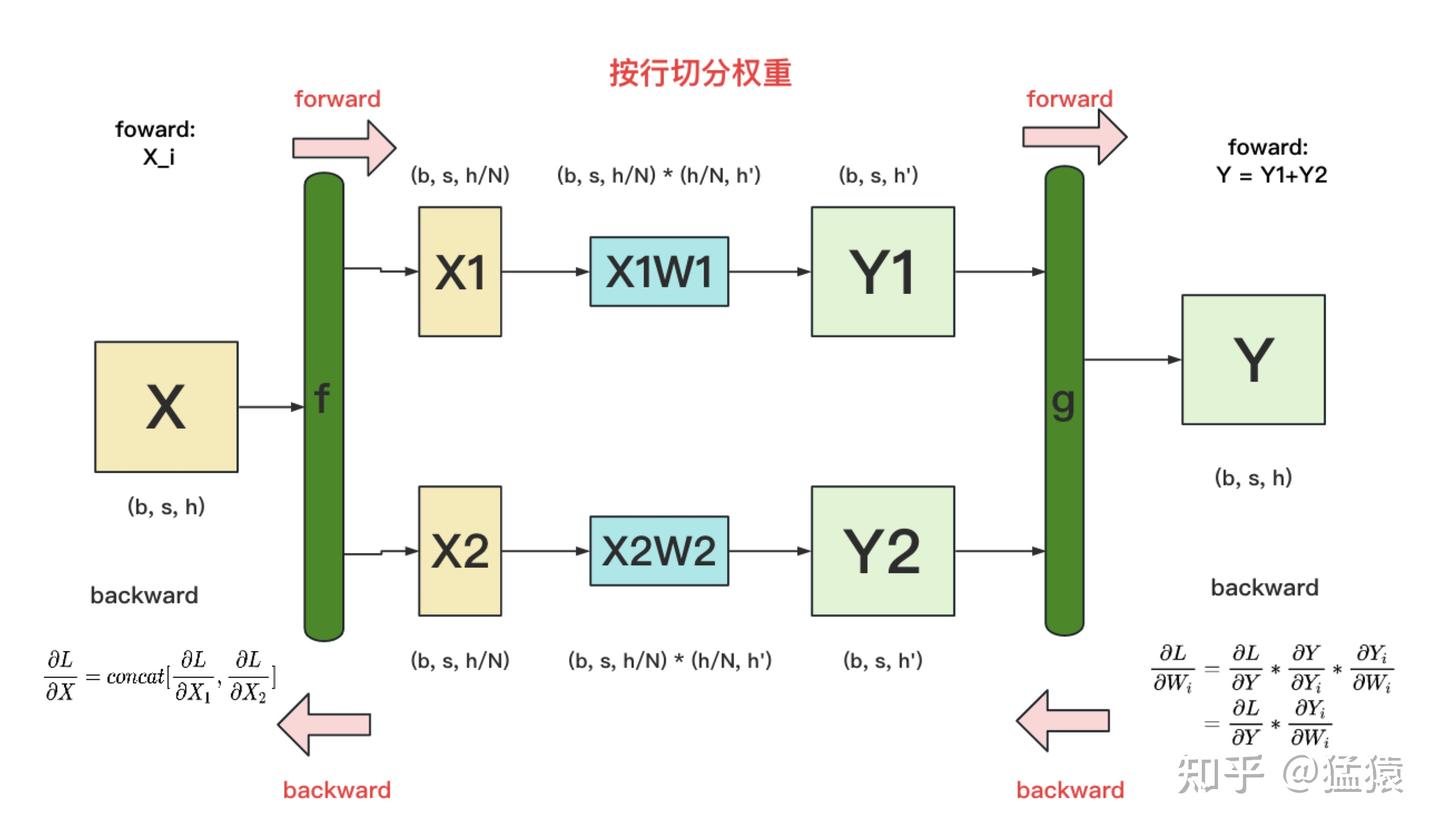
f:
- forward 方法:按列维度对输入执行 split(切分)操作;
- backward 方法:对梯度执行 all-gather(全收集)操作
-
g:
- forward 方法:对输出执行 AllReduce(全归约)操作;
- backward 方法:直接输出梯度,无需执行任何通讯操作(原因:经过 g 的 forward 阶段后,每块 GPU 上已持有 Yi 和 Y,依据 g 的 backward 公式,每块 GPU 可独立完成梯度计算,无需跨卡通讯)
-
代码实现
class RowParallelLinear(torch.nn.Module):
    """Linear layer with row parallelism.

    The linear layer is defined as Y = XA + b. A is parallelized along
    its first dimension and X along its second dimension as:
               -   -
              | A_1 |
              | .   |
          A = | .   |        X = [X_1, ..., X_p]
              | .   |
              | A_p |
               -   -
    Arguments:
        input_size: first dimension of matrix A.
        output_size: second dimension of matrix A.
        bias: If true, add bias. Note that bias is not parallelized.
        input_is_parallel: If true, we assume that the input is already
                           split across the GPUs and we do not split
                           again.
        init_method: method to initialize weights. Note that bias is always set
                     to zero.
        stride: For the strided linear layers.
        keep_master_weight_for_test: This was added for testing and should be
                                     set to False. It returns the master weights
                                     used for initialization.
        skip_bias_add: This was added to enable performance optimations where bias
                       can be fused with other elementwise operations. we skip
                       adding bias but instead return it.
    """

    def __init__(
        self,
        input_size,
        output_size,
        bias=True,
        input_is_parallel=False,
        init_method=init.xavier_normal_,
        stride=1,
        keep_master_weight_for_test=False,
        skip_bias_add=False,
        params_dtype=None,
        skip_init=False,
        device=None,
    ):
        super(RowParallelLinear, self).__init__()

        # Keep input parameters
        self.input_size = input_size
        self.output_size = output_size
        self.input_is_parallel = input_is_parallel
        # Divide the weight matrix along the last dimension.
        world_size = get_tensor_model_parallel_world_size()
        self.input_size_per_partition = divide(input_size, world_size)
        self.skip_bias_add = skip_bias_add
        self.params_dtype = params_dtype
        self.device = device

        # Parameters.
        # Note: torch.nn.functional.linear performs XA^T + b and as a result
        # we allocate the transpose.
        # Initialize weight.
        args = get_args()
        if not skip_init:
            if args.use_cpu_initialization:
                self.weight = Parameter(
                    torch.empty(
                        self.output_size,
                        self.input_size_per_partition,
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )
                self.master_weight = _initialize_affine_weight_cpu(
                    self.weight,
                    self.output_size,
                    self.input_size,
                    self.input_size_per_partition,
                    1,
                    init_method,
                    stride=stride,
                    return_master_weight=keep_master_weight_for_test,
                )
            else:
                self.weight = Parameter(
                    torch.empty(
                        self.output_size,
                        self.input_size_per_partition,
                        device=self.device if self.device is not None else torch.cuda.current_device(),
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )
                _initialize_affine_weight_gpu(
                    self.weight, init_method, partition_dim=1, stride=stride
                )
        else:
            self.register_parameter("weight", None)

        if bias and not skip_init:
            if args.use_cpu_initialization:
                self.bias = Parameter(
                    torch.empty(self.output_size,
                                dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype)
                )
            else:
                self.bias = Parameter(
                    torch.empty(
                        self.output_size,
                        device=self.device if self.device is not None else torch.cuda.current_device(),
                        dtype=self.params_dtype if self.params_dtype is not None else args.params_dtype,
                    )
                )
            # Always initialize bias to zero.
            with torch.no_grad():
                self.bias.zero_()
        else:
            self.register_parameter("bias", None)

    def forward(self, input_):
        # Set up backprop all-reduce.
        if self.input_is_parallel:
            input_parallel = input_
        else:
            input_parallel = scatter_to_tensor_model_parallel_region(input_)
        # Matrix multiply.
        output_parallel = F.linear(input_parallel, self.weight)
        # All-reduce across all the partitions.
        output_ = reduce_from_tensor_model_parallel_region(output_parallel)
        if not self.skip_bias_add:
            output = output_ + self.bias if self.bias is not None else output_
            output_bias = None
        else:
            output = output_
            output_bias = self.bias
        return output, output_bias

# 行切割中的f和g算子
class _ScatterToModelParallelRegion(torch.autograd.Function):
    """Split the input and keep only the corresponding chuck to the rank."""
    # 行切割中的f算子
    # forward:沿列split输入
    # backward:all-gather梯度
    @staticmethod
    def symbolic(graph, input_):
        return _split(input_)

    @staticmethod
    def forward(ctx, input_):
        return _split(input_)

    @staticmethod
    def backward(ctx, grad_output):
        return _gather(grad_output)

class _ReduceFromModelParallelRegion(torch.autograd.Function):
    """All-reduce the input from the model parallel region."""
    # 行切割中的g算子
    # forward:AllReduce输出
    # backward:正常计算梯度,GPU间无需做任何通讯
    @staticmethod
    def symbolic(graph, input_):
        return _reduce(input_)

    @staticmethod
    def forward(ctx, input_):
        return _reduce(input_)

    @staticmethod
    def backward(ctx, grad_output):
        return grad_output
ParallelSelfAttention
-
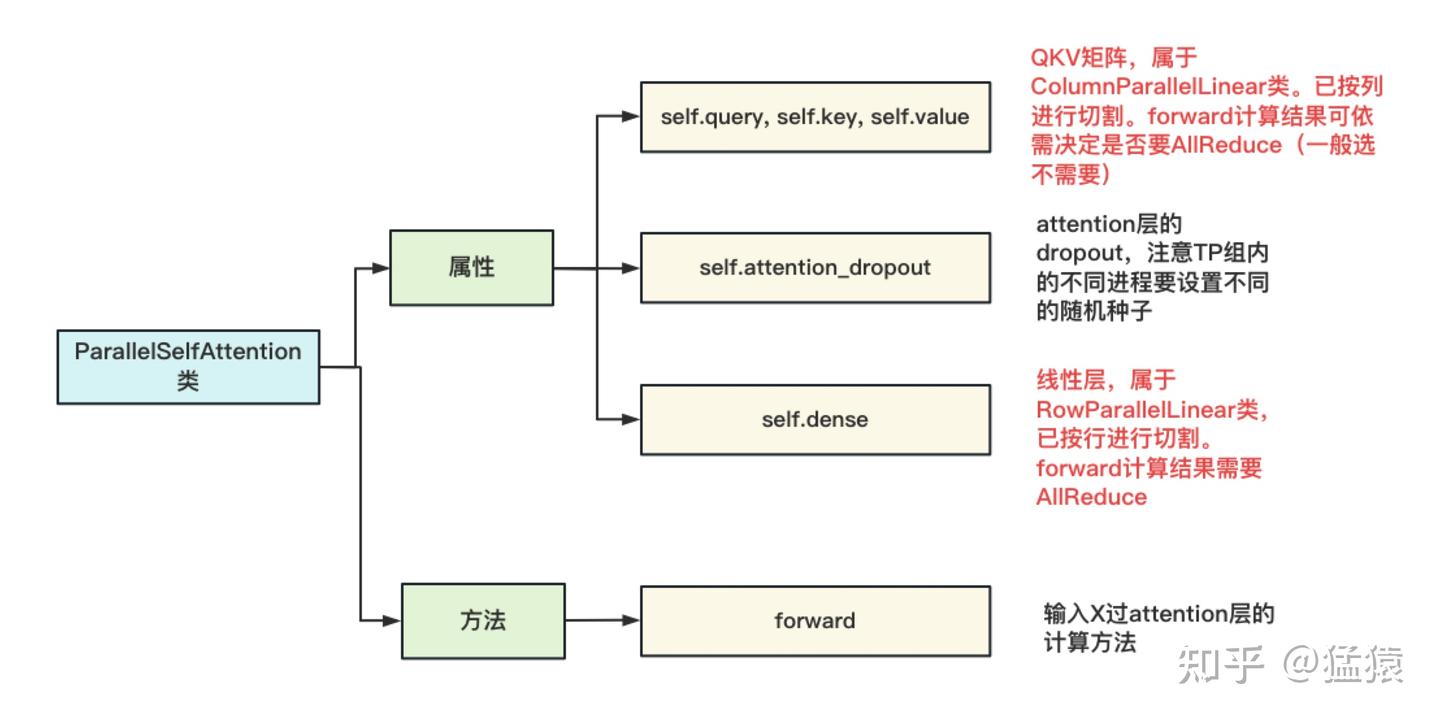
每个进程上维护的都是按列切割完的 QKV 矩阵,进程间独立计算,QKV 矩阵的输出结果一般不做 AllReduce
-
每个进程上维护的是按行切割的线性层矩阵,Attention 输出经过线性层后的结果做 AllReduce
-
在设置 attention_dropout 时,同样调用了 get_cuda_rng_tracker 方法,令 TP 组内的进程拥有不同的随机种子
-
线性层后的 dropout 去哪里了?代码里把它定义到了 ParallelTransformerLayer 下(等于 attention + mlp)
ParallelMLP
ParallelTransformerLayer
ParallelTransformer
_VocabParallelCrossEntropy
-
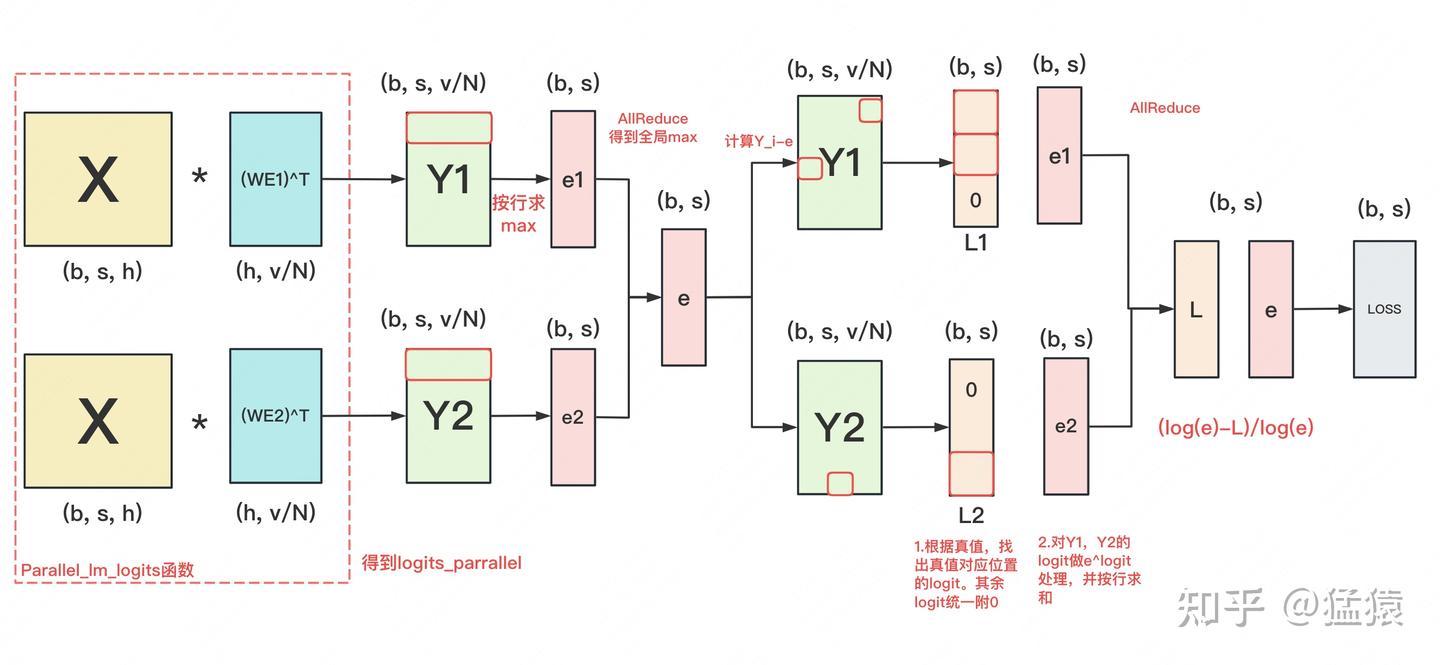
Megatron 中的交叉熵计算流程
-
在 Transformer 中,输出层会额外训练一个线性矩阵,来计算 logit;而此处,可以用输入层 WE 的转置来代替这个线性矩阵
-
这是由于在 Megatron 交叉熵的计算逻辑中,可以将 结果理解成 “X 与 WE 间的相似度”,例如对 Y1 来说,它的第一行中的每个 logit,表示第一个 token 与词表里每个词的相似度
-
注意到每个进程上只维护部分 WE
- 例如,假设词表共有 10 个单词,WE1 维护前 5 个单词,WE2 维护后 5 个单词
- 因此,对 Y1,它的第一行中的每个 logit,表示第一个 token 与词表中前 5 个词的相似度;对 Y2,它的第一行中的每个 logit,表示第一个 token 与词表中后 5 个词的相似度
-
首先求解最大值,得到基于全局的最大 logit 值,再进行减法来防止计算溢出
-
在这里,all-reduce 操作是取全局最大值,而不是进行相加操作
-
Softmax 中「减去最大值」的核心目的是:把所有 logits 调整到
≤ 0的范围,避免exp(x)因x过大导致数值上溢(比如exp(1000)会直接变成无穷大) -
接下来进行真值与局部 logit 提取
- 每个进程(GPU)都持有一份维度为
(b, s)的真值标签,其中b为 batch size,s为序列长度,每个元素代表对应 token 的目标词 ID - 每个进程仅维护词表权重
WE的一个分片(如WE1或WE2),因此本地 logit 矩阵Y_i(维度为(b, s, v/N))只覆盖词表的一部分 - 我们需要在本地
Y_i中,仅提取与真值词 ID 对应的 logit 值:- 例如,若序列长度为 3,前两个 token 的真值词 ID 落在进程 1 的词表分片
WE1中,第三个 token 的真值词 ID 落在进程 2 的词表分片WE2中 - 进程 1 会在
Y1的前两行中,取出对应真值位置的 logit;进程 2 会在Y2的最后一行中,取出对应真值位置的 logit
- 例如,若序列长度为 3,前两个 token 的真值词 ID 落在进程 1 的词表分片
- 与真值位置不对应的元素统一填充为 0,从而得到局部真值 logit 矩阵
L1和L2
- 每个进程(GPU)都持有一份维度为
-
然后进行全局真值 logit 聚合
- 对
L1和L2执行AllReduce操作(使用 Sum 算子),得到全局真值 logit 矩阵L L中每行的数值,表示对应 token 与目标真值词之间的相似度(logit)
- 对
-
全局归一化项计算
-
对每个进程的本地 logit 矩阵
Y1和Y2,按行计算指数和: -
得到局部归一化项
e1和e2 -
对
e1和e2执行AllReduce操作(使用 Sum 算子),得到全局归一化项e -
e中每行的数值,表示对应 token 与词表中所有词的相似度(logit)之和
-
-
我们的优化目标是最小化以下损失值:
-
其中:
- 分子
e - L表示 “token 与所有词的相似度总和” 减去 “token 与真值词的相似度”,代表了模型预测与真实目标之间的差距 - 分母
e作为归一化项,确保损失值在 [0, 1] 范围内,便于训练和梯度传播
- 分子
-
代码实现
class _VocabParallelCrossEntropy(torch.autograd.Function):
    """
    分布式计算Loss
    """
    @staticmethod
    def forward(ctx, vocab_parallel_logits, target):
        # 1. logit - global max(logit)操作,主要目的是防溢出
        logits_max = torch.max(vocab_parallel_logits, dim=-1)[0] # (b, s, 1)
        torch.distributed.all_reduce( # (b, s, 1)
            logits_max,
            op=torch.distributed.ReduceOp.MAX, # 找全局最大值
            group=get_tensor_model_parallel_group(),
        )
        # Subtract the maximum value.
        vocab_parallel_logits.sub_(logits_max.unsqueeze(dim=-1)) # 原始GPU上维护的logits减去每行最大值(防止溢出)

        # 2、根据当前进程id,取出当前进程所维护词表序号等信息
        # 函数,能够获取当前进程所维护词表的start_index和end_index
        get_vocab_range = VocabUtility.vocab_range_from_per_partition_vocab_size
        # 这块GPU上logits最后一维的大小,等于所维护的词表的大小(v/N)
        partition_vocab_size = vocab_parallel_logits.size()[-1]
        # 取得当前进程所在TP组中的序号
        rank = get_tensor_model_parallel_rank()
        # 取得当前进程所在TP组的总进程数
        world_size = get_tensor_model_parallel_world_size()
        # 取得当前进程所维护的词表的start_index和end_index
        vocab_start_index, vocab_end_index = get_vocab_range(
            partition_vocab_size, rank, world_size
        )

        # 3. 基于真值,取出每个token在真值位置上的logit(即和真值的相似度)
        # Create a mask of valid vocab ids (1 means it needs to be masked)
        target_mask = (target < vocab_start_index) | (target >= vocab_end_index) # target = (b, s)
        masked_target = target.clone() - vocab_start_index
        masked_target[target_mask] = 0

        # Get predicted-logits = logits[target].
        # For Simplicity, we convert logits to a 2-D tensor with size
        # [*, partition-vocab-size] and target to a 1-D tensor of size [*].
        logits_2d = vocab_parallel_logits.view(-1, partition_vocab_size) # (b*s, v/N)
        masked_target_1d = masked_target.view(-1) # (b*s)
        arange_1d = torch.arange( # [b*s]
            start=0, end=logits_2d.size()[0], device=logits_2d.device
        )
        # logits_2d[arange_1d, masked_target_1d]:
        # tensor的切片操作。arange_1d:取出所有的行。masked_target_1d:取出logit
        predicted_logits_1d = logits_2d[arange_1d, masked_target_1d] # (b*s)
        predicted_logits_1d = predicted_logits_1d.clone().contiguous()
        predicted_logits = predicted_logits_1d.view_as(target) # (b, s)
        predicted_logits[target_mask] = 0.0
        # All reduce is needed to get the chunks from other GPUs.
        torch.distributed.all_reduce( # allreduce之后得到的logit矩阵为(b, s),每一个位置表示对应真值位置的预测logit
            predicted_logits,
            op=torch.distributed.ReduceOp.SUM,
            group=get_tensor_model_parallel_group(),
        )

        # Sum of exponential of logits along vocab dimension across all GPUs.
        exp_logits = vocab_parallel_logits # (b, s, v/N)
        torch.exp(vocab_parallel_logits, out=exp_logits)
        sum_exp_logits = exp_logits.sum(dim=-1) # (b, s)
        torch.distributed.all_reduce(
            sum_exp_logits,
            op=torch.distributed.ReduceOp.SUM,
            group=get_tensor_model_parallel_group(),
        )

        # 4. 计算Loss = log(sum(exp(logits))) - predicted-logit.
        loss = torch.log(sum_exp_logits) - predicted_logits # (b, s)

        # Store softmax, target-mask and masked-target for backward pass.
        exp_logits.div_(sum_exp_logits.unsqueeze(dim=-1))
        ctx.save_for_backward(exp_logits, target_mask, masked_target_1d)

        return loss

    @staticmethod
    def backward(ctx, grad_output):

        # Retreive tensors from the forward path.
        softmax, target_mask, masked_target_1d = ctx.saved_tensors

        # All the inputs have softmax as their gradient.
        grad_input = softmax
        # For simplicity, work with the 2D gradient.
        partition_vocab_size = softmax.size()[-1]
        grad_2d = grad_input.view(-1, partition_vocab_size)

        # Add the gradient from matching classes.
        arange_1d = torch.arange(start=0, end=grad_2d.size()[0], device=grad_2d.device)
        grad_2d[arange_1d, masked_target_1d] -= 1.0 - target_mask.view(-1).float()

        # Finally elementwise multiplication with the output gradients.
        grad_input.mul_(grad_output.unsqueeze(dim=-1))

        return grad_input, None
分布式混合精度训练
- 混合精度训练的目的主要是为了节省显存消耗
- 训练过程中,模型的哪些部分产生了显存消耗?
- 具体消耗的显存大小,要如何计算?
- 参数占用存储的大小,与参数数值的表达精度密切相关
FP16
-
fp16 又被称为半精度 (half-precision) 浮点表示
- 一共由 16 个 bit 组成(2 bytes),这些 bit 又可以被拆成 3 部分:
sign位:符号表示位,占 1 bitexponent位:指数表示位,占 5 bitfraction位:小数表示位,占 10 bit
-
将 fp16 转换成数值
-
如果 exponent 全为 0,此时数值范围很小
-
如果 fraction 位全为 0,则表示数字 0
-
如果 fraction 位不全为 0,则表示一个很小的数字(fraction 表示由 fraction 位的 bitmap 换算成十进制后的结果)
-
-
如果 exponent 位全为 1,此时意味着表达的数值可能非常大
- 如果 fraction 位全为 0,则表示 ±inf(超过了 FP16 的表达范围)
- 如果 fraction 不全为 0,则表示 NAN
-
其他情况
-
-
计算示例
Binary Hex Value Notes 0 00000 0000000000 0000 0 0 00000 0000000001 0001 smallest positive subnormal number 0 00000 1111111111 03ff largest subnormal number 0 00001 0000000000 0400 smallest positive normal number 0 01101 0101010101 3555 nearest value to 1/3 0 01110 1111111111 3bff largest number less than one 0 01111 0000000000 3c00 one 0 01111 0000000001 3c01 smallest number larger than one 0 11110 1111111111 7bff largest normal number 0 11111 0000000000 7c00 infinity 1 00000 0000000000 8000 1 10000 0000000000 c000 1 11111 0000000000 fc00 negative infinity -
fp16 的表达范围是:5.95e⁻⁸ ~ 65504(取的是绝对值的表达范围,负向同理),超过这个表达范围,则会发生数据的上溢和下溢情况
FP32
-
fp32 又被称为单精度 (single-precision) 浮点表示,是深度学习中标准的精度表示
-
它由 32 bit 组成(4 bytes),这些 bit 可拆分为 3 部分:
-
sign 位:符号表示位,占 1 bit
-
exponent 位:指数表示位,占 8 bit
-
fraction 位:小数表示位,占 23 bit
-
-
fp32 无论是从数值表示范围,还是从数值表示精度上来看,都要比 fp16 更宽广和精准,其数值表示范围约为
BF16
-
bf16 又被称为 brain 浮点表示,它是由 Google Brain 团队研发制定的精度表示方法
-
从图中可以发现,bf16 拥有和 fp16 一样的表示位宽(16 bit,共 2 bytes),但其数值表达范围却和 fp32 一致()
-
这是因为 bf16 相当于从 fp32 中对 fraction 部分做截取而来,因此它的 exponent 部分和 fp32 是一致的
-
exponent 部分决定了数值的表达范围,这也就意味着 bf16 的表达范围和 fp32 一致
-
对比 bf16 和 fp16:bf16 的 exponent 位更多了,fraction 位更少了;这意味着 bf16 表达的数值范围比 fp16 更宽广,但其表达精度却不如 fp16
Format Epsilon (ε) FP32 0.00000012 FP16 0.00097656 BF16 0.00781250 -
Epsilon 是各浮点表示形式下使得 成立的最小浮点数值
-
bf16 的表达精度不如 fp16 和 fp32,那会出现什么问题呢?
- 尽管 BF16 的数值精度低于 FP16 和 FP32,这在理论上可能对模型收敛产生一定影响,但在实际训练中,其表现却相当稳健
- 核心原因在于,对模型训练过程而言,数值表示范围的宽广度往往比单纯的精度更为关键
- 当数值范围不足时,极易引发上溢(inf)或下溢(nan)问题,导致对应训练步骤失效,而包含非法值的梯度也无法用于有效更新模型权重
- 简言之,只有确保数值处于合理的表示范围内,进一步讨论精度才有实际意义
-
不同精度的表达方式做一个总结:
- 占用存储:fp16 与 bf16 均占用 2 bytes,而 fp32 占用 4 bytes
- 数值表达范围:fp32 = bf16 > fp16
- 数值表达精度:fp32 > fp16 > bf16
-
在深度学习训练中,标准精度通常为 fp32;为了节省存储、提升训练速度,混合精度训练(即 fp32 + fp16/bf16)被广泛采用
混合精度训练
-
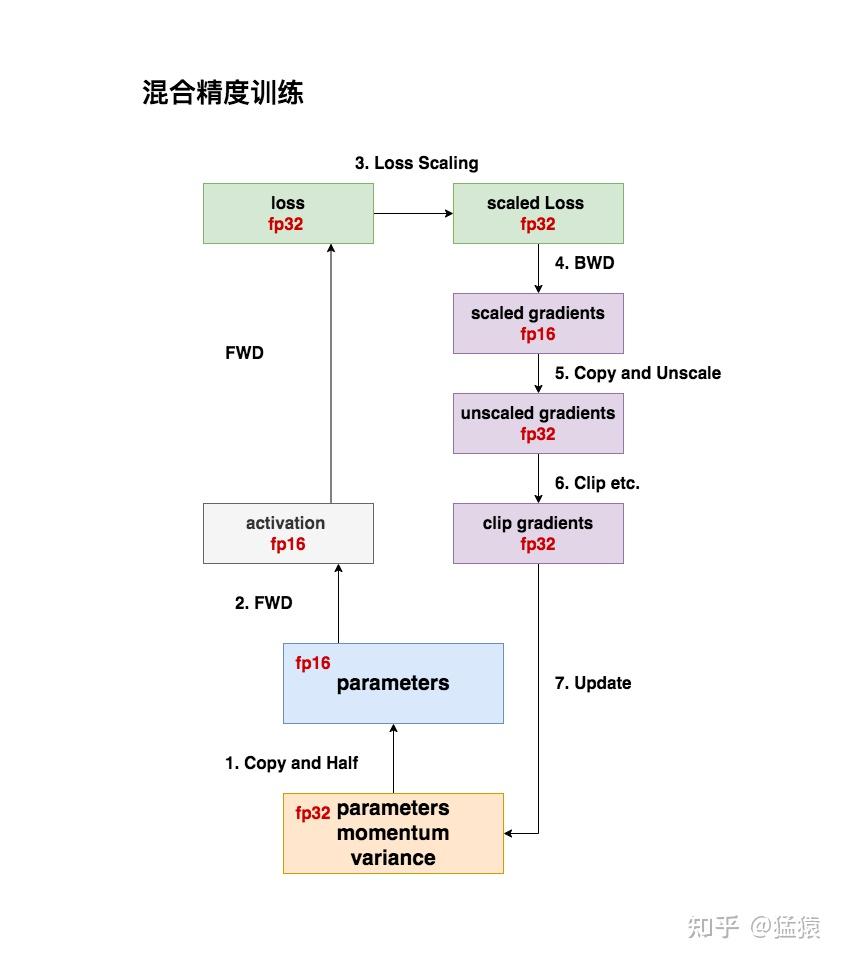
Megatron 的混合精度训练流程如下
-
首先,进行计算准备
- 首先存储一份 FP32 精度的参数(parameter)、动量(momentum)和方差(variance)
- 基于该 FP32 参数复制一份副本,并将其精度降至 FP16,得到 FP16 精度的参数
- FP32 精度的参数作为「主权重」(Megatron 源码中命名为
main_param):在模型训练阶段,optimizer.step()执行的权重更新操作针对的是该主权重;训练完成后,最终保存的也是这份权重,获取高精度权重是训练的核心目标 - FP16 精度的参数作为「训练权重」(Megatron 源码中命名为
model_param),是训练过程中实际参与前向传播计算的权重 - 混合精度训练的核心思想即在于此:训练全程无需始终维持单精度(FP32)权重参与计算,通过半精度(FP16)权重配合特定策略,既能保证训练顺利收敛,又可有效节省显存占用、提升训练速度
-
前向计算
- 使用 FP16 参数执行前向计算,过程中生成的激活值(activation)也为 FP16 精度,这些激活值将用于后续反向传播
- 需特别注意:若未采用重计算(recompute)等显存优化策略,激活值占用的存储空间可能远超模型本身
- 为保证梯度计算的精度,最终输出的损失(loss)以 FP32 精度表示
-
损失计算
- 为防止梯度溢出(主要是下溢),对 FP32 精度的 loss 进行 scale 处理,得到 FP32 精度的 scaled loss
-
反向传播(BWD)
- 基于 FP32 精度的 scaled loss 执行反向传播,计算得到的梯度为 scaled gradients
- 为节省显存,这些 scaled gradients 以 FP16 精度存储
-
梯度反缩放(Unscaled gradients)
- 梯度以 FP16 精度存储,但在用于更新模型权重前,必须转换为 FP32 精度,并同时执行 unscale 操作,将梯度恢复至原始值
- 理论上说,当梯度从 fp16 转变为 fp32 时,fp16 的梯度已经没用了,因此可以将其从存储中移除
-
梯度裁剪(Clip gradients)
- 将梯度转换为 FP32 精度后,可执行梯度裁剪(clip)操作,以此进一步规避梯度爆炸或梯度消失问题
-
混合精度训练下的存储计算
-
此处先忽略 FP16 的激活值
-
设 表示模型参数量,显存大小单位为字节
分类 大小 大小总计 必存 parameter (fp32) 4Φ 12Φ momentum (fp32) 4Φ variance (fp32) 4Φ 中间值 parameter (fp16) 2Φ 4Φ gradients (fp16) 2Φ 总计 16Φ
-
Loss Scale
-
为什么要做混合精度训练?
-
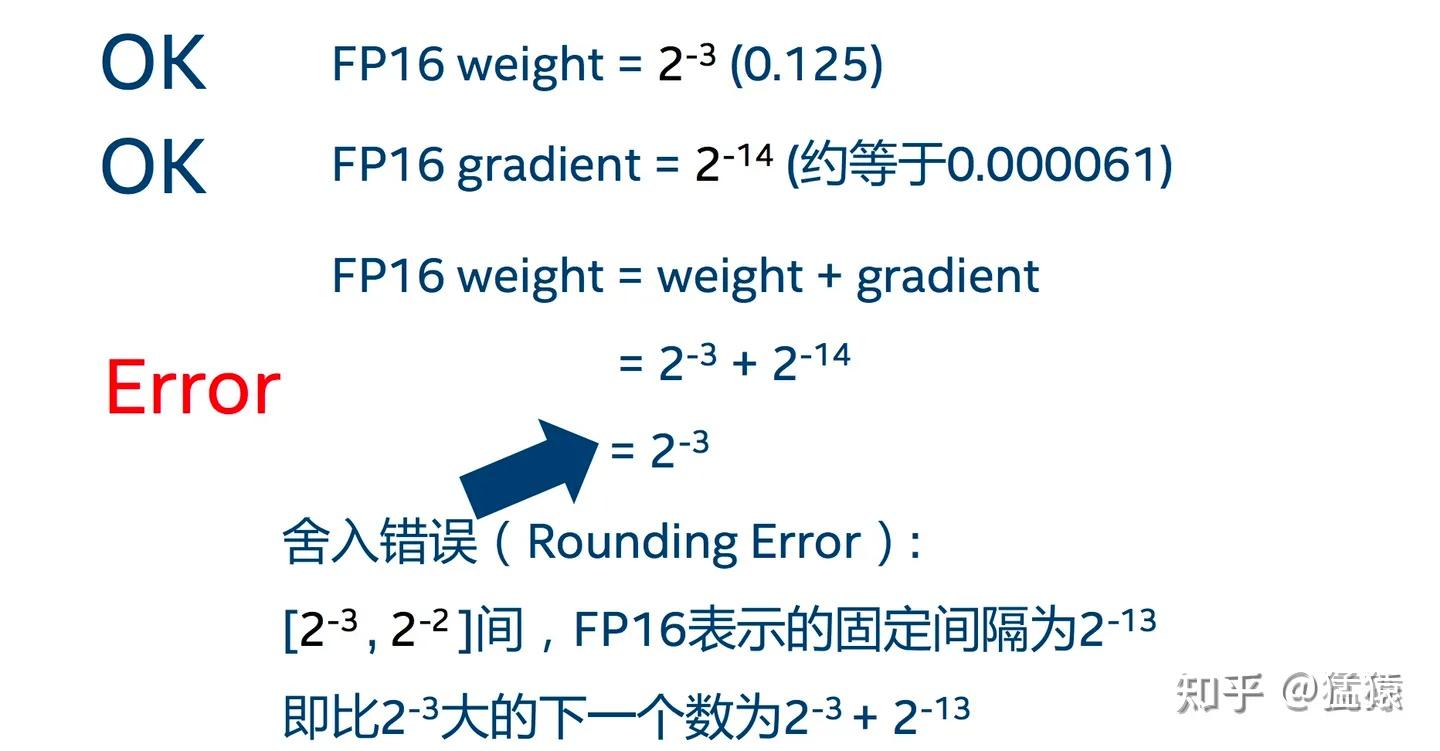
舍入误差的存在
-
假设在 FP16 条件下,某权重为 ,对应梯度为 ,执行梯度更新时(忽略学习率),理论上更新结果应为:
-
但在实际计算中,由于 FP16 的舍入误差,这一更新会被近似为 ,导致权重看似没有变化
-
这是因为 FP16 的尾数精度有限,当梯度的数量级远小于权重本身时,梯度的贡献会被舍入误差完全抵消,使得本轮训练对权重更新没有任何实际影响,相当于 “白训练” 了
-
-
梯度下溢
- 在训练后期,约有 67% 的梯度值会小于 ,而这恰好是 FP16 数值表示范围的下界
- 这意味着若全程使用 FP16 进行训练,训练后期会频繁出现梯度下溢,导致训练过程无法正常进行
-
针对舍入误差问题
- 可在更新模型权重时,将梯度从 FP16 转换为 FP32 后再执行更新,转换后的 FP16 权重可释放存储
- 这种方式既满足了计算过程中节省显存、加速训练的目标,又解决了因舍入误差导致的模型权重无法正常更新的问题
-
针对梯度下溢问题
- 常用手段是 Loss Scale,其核心思想是:将 Loss 放大 N 倍,计算出的梯度也会随之放大 N 倍,从而避免梯度下溢
-
混合精度训练并非所有模型参数都以 FP16 形式参与训练:
- 例如 Layer Norm / Batch Norm 的参数通常保持 FP32 形式;
- Loss 也保持 FP32 形式
- 主要原因是这些数值的精度对训练过程影响较大,且存储占用不大,因此维持高精度形式更优
-
若将 FP16 替换为 BF16,是否还需要 Loss Scale?
- BF16 与 FP32 的数值表达范围一致,仅表达精度有所欠缺
- 由于不存在梯度下溢问题,使用 BF16 时可以不采取 Loss Scale,或使用常量 Loss Scale(如 Megatron 框架的实现)
-
常量损失放大
-
若训练全程采用固定的缩放因子
loss_scale对损失(Loss)进行缩放,该策略被称为「常量损失放大」,具体执行流程如下: -
损失放大阶段(Scale up):在反向传播(backward)阶段,将 Loss 值放大 倍,基于放大后的 Loss 计算梯度,并将梯度以 FP16 精度存储(兼顾显存效率)
-
梯度反缩放阶段(Scale down),当需要用梯度更新权重时,执行以下操作:
-
梯度校验:先检查放大后的梯度是否出现上溢(inf/nan)—— 尽管放大 Loss 解决了梯度下溢问题,但可能引发梯度上溢;
-
权重更新判定:
- 若梯度存在上溢,直接跳过本轮(step)的权重更新;
- 若梯度无异常,则对 FP16 梯度执行反缩放(unscale):将梯度值缩小 倍,并转换为 FP32 精度,用于本轮权重更新
-
-
-
常量损失放大的核心问题
-
该策略看似可行,但存在一个关键缺陷:固定
loss_scale的取值难以适配训练全程 -
若
loss_scale过小,无法有效解决梯度下溢问题 -
若
loss_scale过大,极易触发梯度上溢,导致大量训练步骤失效
-
-
由此引申出一个核心需求:是否存在一种自适应策略,让模型在训练过程中自主探索、动态调整
loss_scale,以平衡梯度下溢与上溢的风险? -
动量损失放大
- 该方法的核心目标是动态地找到一个尽可能大的 loss_scale,在解决梯度下溢的同时,最大限度地避免梯度上溢
- 初始化:从一个较大的初始值(如 )开始,用放大后的 Loss 计算梯度
- 梯度检查:检查放大后的梯度是否出现上溢(
inf/nan)- 无上溢:将梯度反缩放为 FP32,正常执行权重更新
- 出现上溢:跳过本轮权重更新,并将
loss_scale缩小 倍( 默认为 2)
- 后期调整:在训练后期,梯度波动趋于稳定,可尝试每 次迭代( 默认为 2000)将
loss_scale放大 倍;若再次出现上溢,则回退到放大前的状态,以此类推 - 如果在训练初期发现模型偶尔出现 inf/nan 的情况,其实这是正常的,因为动量策略本身就是一个探索性的策略
-
Megatron 同样提供了常量和动态两种损失放大方法,其对动态方法的改动如下
参数名 含义说明 self._scale初始化的损失缩放因子(loss scale),是动态调整的核心变量 self.min_scaleloss scale 的最小值,限制缩放因子不会被过度缩小 self.growth_interval连续无梯度上溢的迭代次数阈值,达到该阈值则尝试增大 loss scale self.growth_factor放大系数:当连续 growth_interval次无梯度上溢时,loss scale 扩大该倍数self.hysteresis允许累计出现梯度上溢的最大迭代次数(非连续) self.backoff_factor缩小系数:当累计上溢次数达 hysteresis时,loss scale 缩小该倍数 -
Megatron 的逻辑
- 放大逻辑:若连续
self.growth_interval次迭代均未出现梯度上溢(inf/nan),则将self._scale乘以self.growth_factor,以此尝试更大的缩放因子,最大化解决梯度下溢问题 - 缩小逻辑:统计梯度上溢的累计次数,当累计次数达到
self.hysteresis时:- 执行缩放因子缩小操作:
self._scale = torch.max(self._scale * self.backoff_factor, self.min_scale); - 缩小后重置梯度上溢的累计次数,重新开始计数;
torch.max(...)保证缩小后的self._scale不会低于self.min_scale,避免缩放因子过小失效
- 执行缩放因子缩小操作:
- 放大逻辑:若连续
梯度裁剪
-
单个梯度固定阈值裁剪
- 做法:设定阈值范围(如
min=-1, max=1),对每个梯度值单独判断:- 若梯度小于
min,则置为min; - 若梯度大于
max,则置为max
- 若梯度小于
- 难点:阈值的选取依赖经验,难以找到普适的最优值
- 做法:设定阈值范围(如
-
基于梯度向量范数的裁剪(L2 范数裁剪)
-
定义梯度向量:设 ,,则梯度向量 ,其 L2 范数为:
-
裁剪规则:设定裁剪阈值
-
当 时:
-
即对梯度向量进行等比例缩放,使其范数恰好等于
-
当 时:梯度保持不变
-
-
-
缩放因子 是一个标量,其作用与学习率 类似,都是对梯度进行缩放以控制更新步长
优化器实现
-
调用
optimizer/__init__.py/get_megatron_optimizer,将返回一个能够做分布式混合精度训练的 optimizer -
代码实现
def get_megatron_optimizer(model): args = get_args() # --------------------------------------------------------------- # 不对CPU做分布式optimizer # --------------------------------------------------------------- if args.cpu_optimizer: raise NotImplementedError("need to add cpu adam") # ------------------------------------------------------------------ # 将模型权重分为“需要做衰减/不需要做衰减”两部分。 # LN和bias不做权重衰减,其余系数正常做衰减 # param_groups = (weight_decay_params, no_weight_decay_params) # 复习一下模型并行代码篇讲过的内容:这里的param不是全量param,是根据当前进程id # 切割好的param # 权重衰减的本质是为了防止过拟合,对权重衰减不了解的朋友,可参考: # https://blog.csdn.net/program_developer/article/details/80867468 # ------------------------------------------------------------------ param_groups = _get_params_for_weight_decay_optimization(model) # ------------------------------------------------------------------ # 根据需求,设定adam/sgd优化器 # ------------------------------------------------------------------ if args.optimizer == "adam": optimizer = Adam( param_groups, lr=args.lr, weight_decay=args.weight_decay, betas=(args.adam_beta1, args.adam_beta2), eps=args.adam_eps, ) elif args.optimizer == "sgd": optimizer = SGD( param_groups, lr=args.lr, weight_decay=args.weight_decay, momentum=args.sgd_momentum, ) else: raise Exception("{} optimizer is not supported.".format(args.optimizer)) # ------------------------------------------------------------------ # 如果使用了deepspeed,那optimizer就交给它做后续处理 # ------------------------------------------------------------------ if args.deepspeed: return optimizer # ------------------------------------------------------------------ # 如果未使用deepspeed,就手动写后续混合精度处理代码 # params_have_main_grad表示在使用torch DDP的过程中,是否曾通过连续buffer # 来存储数值。 # 如果否,则梯度照常存在tensor.grad下 # 如果是,则梯度存在tensor.main_grad下 # 我们在下文会更详细介绍这块 # ------------------------------------------------------------------ params_have_main_grad = False if args.DDP_impl == "local": params_have_main_grad = True # ------------------------------------------------------------------ # 如果我们使用混合精度训练,即训练过程中用fp16/bf16 # ------------------------------------------------------------------ if args.fp16 or args.bf16: # --------------------------------------------------------------------------------------- # 设置grad scaler(即本文3.3中所说的loss scale策略) # 1、如果我们提供了loss_scale(args.loss_scale),我们就用它初始化一个常量scaler # 2、如果我们没有提供loss_scale, 且我们在使用fp16,就用一个动态的scaler # 4、如果我们在使用bf16,就不需要loss_scale(原因参见3.3(1)) # --------------------------------------------------------------------------------------- grad_scaler = None # Constant loss scale. if args.loss_scale: grad_scaler = ConstantGradScaler(args.loss_scale) # Dynamic loss scale. else: if args.fp16: grad_scaler = DynamicGradScaler( initial_scale=args.initial_loss_scale, min_scale=args.min_loss_scale, growth_factor=2.0, backoff_factor=0.5, growth_interval=args.loss_scale_window, hysteresis=args.hysteresis, ) # 用于做混合精度训练的optimizer return Float16OptimizerWithFloat16Params( optimizer, args.clip_grad, args.log_num_zeros_in_grad, # 值为0的梯度数量 params_have_main_grad, args.bf16, grad_scaler, ) # --------------------------------------------------------------------------------------- # 不使用混合精度训练,全程都用fp32 # --------------------------------------------------------------------------------------- # FP32. return FP32Optimizer( optimizer, args.clip_grad, args.log_num_zeros_in_grad, params_have_main_grad ) -
params_have_main_grad 参数
- params_have_main_grad = False,则梯度在 tensor.grad 下,这也是一般读取梯度的方式
- params_have_main_grad = True,则梯度在 tensor.main_grad 下,这是手动创建的读取梯度的方式
-
main_grad
main_grad是在model/distributed.py脚本中对 PyTorch 原生 DDP(分布式数据并行)进行重定义后新增的梯度存储属性,其设计核心目标是优化显存空间的利用效率- PyTorch 原生 DDP 中,梯度默认存储在张量的
tensor.grad属性下,但这种存储方式存在缺陷:不同参数的梯度张量在显存中是离散分布的,当显存空间碎片化时,即使总剩余空间足够,也可能因单个梯度张量无法找到连续的存储空间而导致存储失败(OOM 或存储 fail) - 为解决上述问题,重新设计了梯度存储逻辑:
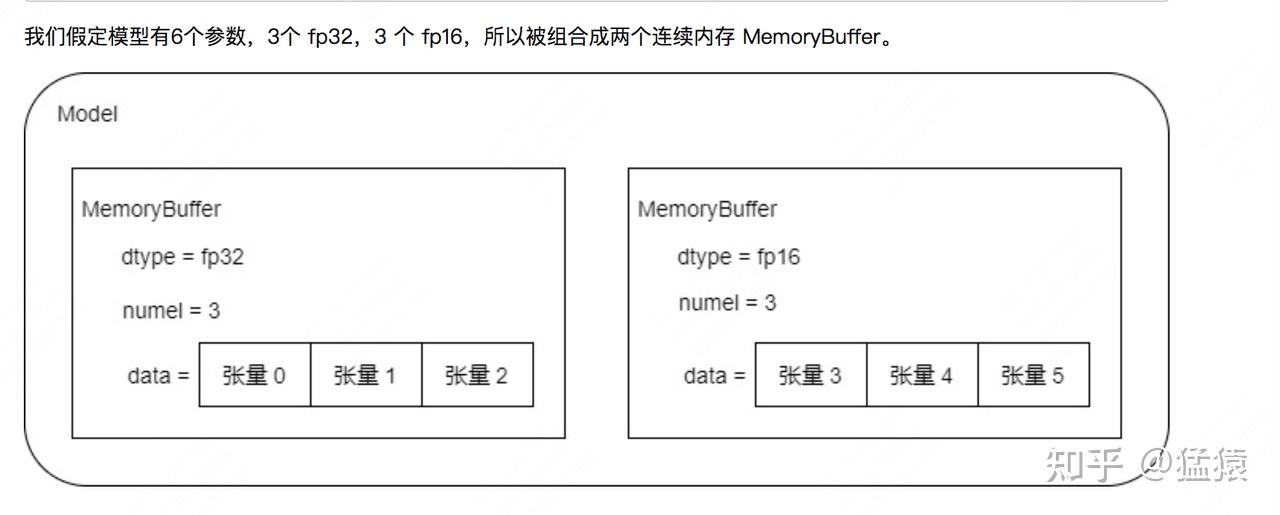
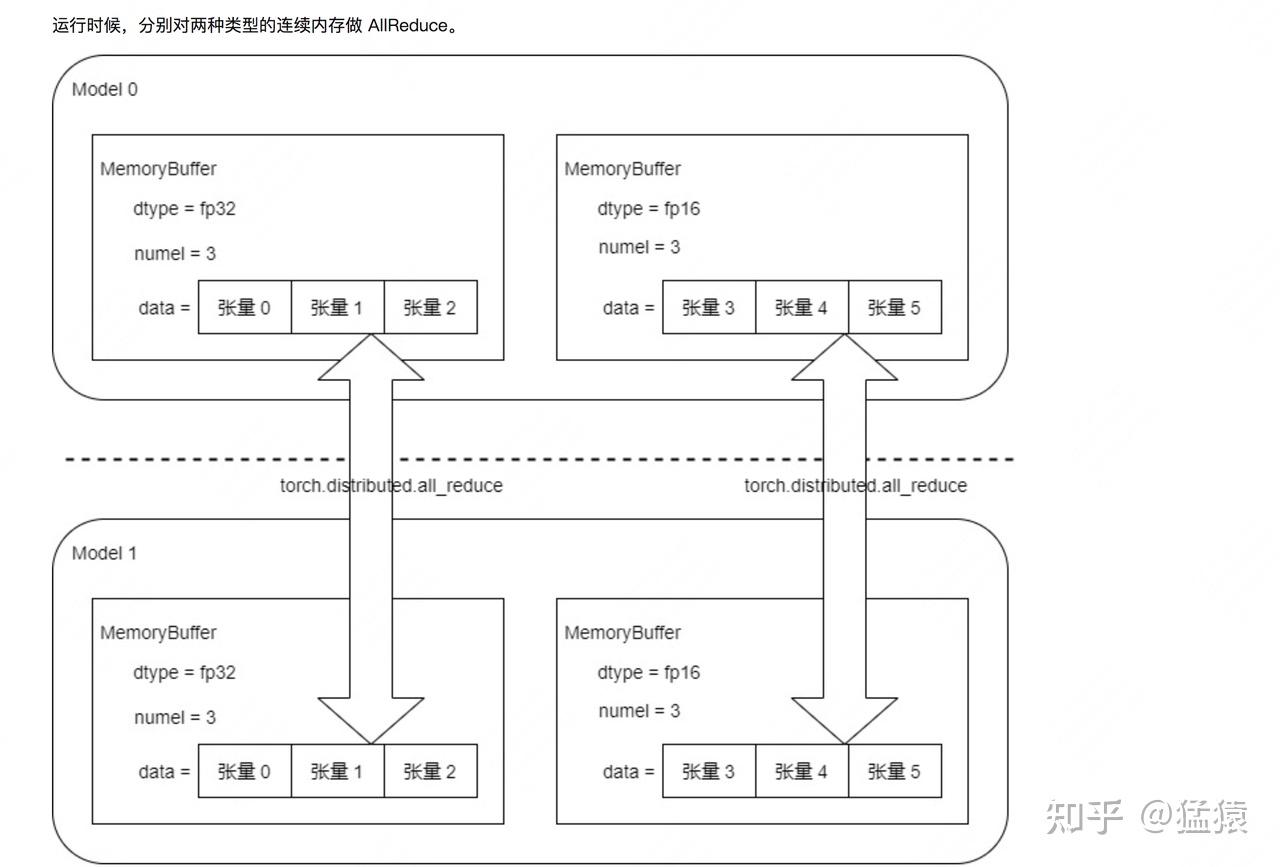
- 将数据类型(dtype)相同的参数梯度集中存放在连续的显存缓冲区(buffer) 中;
- 梯度不再存储在原生的
tensor.grad下,而是统一挂载到自定义属性tensor.main_grad上
main_grad本质上是对梯度存储形式的优化,核心收益是:- 避免显存碎片化导致的存储失败;
- 提升显存空间的利用率,适配大模型分布式训练的显存紧张场景
-
DynamicGradScaler
class MegatronGradScaler(ABC): def __init__(self, initial_scale): """Initialize scale value with the input initial scale. 初始化loss_scale,同时规定loss_scale必须大于0 """ assert initial_scale > 0.0 self._scale = torch.cuda.FloatTensor([initial_scale]) @property def scale(self): return self._scale @property def inv_scale(self): return self._scale.double().reciprocal().float() @abstractmethod def update(self, found_inf): pass @abstractmethod def state_dict(self): pass @abstractmethod def load_state_dict(self, state_dict): pass class DynamicGradScaler(MegatronGradScaler): def __init__( self, initial_scale, min_scale, growth_factor, backoff_factor, growth_interval, hysteresis, ): """ "Grad scaler with dynamic scale that gets adjusted during training. Params: self._scale:表示初始化loss scale self.min_scale:表示loss scale的最小值 self.growth_interval:表示连续无梯度上溢的迭代次数 self.growth_factor:当连续self.growth_interval次未出现梯度上溢时, 就将loss scale扩大self.growth_factor倍 self.hysteresis:表示最多允许出现梯度上溢的迭代次数 self.backoff_factor:当累计出现self.hysteresis次梯度上溢的情况时(注意是累计不是连续), 则将loss scale缩小self.backoff_factor倍。 缩小公式为self._scale = torch.max(self._scale * self.backoff_factor, self.min_scale)。 缩小后重新开始计算梯度上溢的次数。 """ super(DynamicGradScaler, self).__init__(initial_scale) # Lower bound on the scale. assert min_scale > 0.0 assert min_scale <= initial_scale self.min_scale = torch.cuda.FloatTensor([min_scale]) # Growth and backoff factors for the scale. assert growth_factor > 1.0 self.growth_factor = torch.cuda.FloatTensor([growth_factor]) assert backoff_factor < 1.0 assert backoff_factor > 0.0 self.backoff_factor = torch.cuda.FloatTensor([backoff_factor]) # Interval over which if we don't see any inf/nan, # we will scale the grad scale by the growth factor. assert growth_interval > 0 self.growth_interval = growth_interval # Number of inf/nans we should see before scaling down # the grad scale by the backoff factor. assert hysteresis > 0 self.hysteresis = hysteresis # Trackers. self._growth_tracker = 0 self._hysteresis_tracker = self.hysteresis def update(self, found_inf): """ 更新loss scale """ # ------------------------------------------------------------- # 一旦发现梯度溢出(inf/nan)的情况 # ------------------------------------------------------------- if found_inf: self._growth_tracker = 0 self._hysteresis_tracker -= 1 # 如果_hysteresis_tracker变成<=0了, # 说明梯度溢出的次数已经超过了我们设定的阈值, # 这时就要惩罚性地缩小loss_scale 我们就要减少loss_scale if self._hysteresis_tracker <= 0: self._scale = torch.max( self._scale * self.backoff_factor, self.min_scale ) # ------------------------------------------------------------- # 如果没有发现梯度inf/nan # ------------------------------------------------------------- else: # If there is no nan/inf, increment the growth tracker. self._growth_tracker += 1 # 如果我们已经连续多次没有出现inf/nan,我们就可以增大loss scale if self._growth_tracker == self.growth_interval: # Reset the tracker and hysteresis trackers, self._growth_tracker = 0 self._hysteresis_tracker = self.hysteresis # and scale up the loss scale. self._scale = self._scale * self.growth_factor def state_dict(self): state_dict = {} state_dict["scale"] = self._scale state_dict["growth_tracker"] = self._growth_tracker state_dict["hysteresis_tracker"] = self._hysteresis_tracker return state_dict def load_state_dict(self, state_dict): self._scale = state_dict["scale"].cuda(torch.cuda.current_device()) self._growth_tracker = state_dict["growth_tracker"] self._hysteresis_tracker = state_dict["hysteresis_tracker"] -
Float16OptimizerWithFloat16Params 实现
class Float16OptimizerWithFloat16Params(MegatronOptimizer): """Float16 optimizer for fp16 and bf16 data types. Arguments: optimizer: base optimizer such as Adam or SGD clip_grad: clip gradeints with this global L2 norm. Note that clipping is ignored if clip_grad == 0 梯度剪裁的阈值(也就是3.4中说的常量c),如果等于0说明我们不做梯度剪裁 log_num_zeros_in_grad: return number of zeros in the gradients. params_have_main_grad: flag indicating if parameters have a `main_grad` field. If this is set, we are assuming that the model parameters are store in the `main_grad` field instead of the typical `grad` field. This happens for the DDP cases where there is a contihuous buffer holding the gradients. For example for bfloat16, we want to do gradient accumulation and all-reduces in float32 and as a result we store those gradients in the main_grad. Note that main grad is not necessarily in float32. 相关说明见4.1中的解释,注意main_grad并不一定是fp32的 bf16: if true, the model is running in bfloat16. grad_scaler: used for scaling gradients. Note that this can be None. This case happens when `bf16 = True` and we don't use any loss scale. Note that for `bf16 = True`, we can have a constnat gradient scaler. Also for `bf16 = False`, we always require a grad scaler. 当模型是用bf16跑的时候,我们要么用一个常数的loss scale,要么不用loss scale(原因见3.3(1)), 不用的话grad_scaler = None 当模型不是bf16跑的时候,我们一般要用一个loss scale,至于是常数的,还是动态的,就靠自己决定了 """ def __init__( self, optimizer, clip_grad, log_num_zeros_in_grad, params_have_main_grad, bf16, grad_scaler, ): super(Float16OptimizerWithFloat16Params, self).__init__( optimizer, clip_grad, log_num_zeros_in_grad, params_have_main_grad ) self.bf16 = bf16 self.grad_scaler = grad_scaler # ------------------------------------------------------------------- # None grad scaler is only supported for bf16. # 用fp16跑模型时,一定要用loss scale # ------------------------------------------------------------------- if self.grad_scaler is None: assert self.bf16, "fp16 expects a grad scaler." # --------------------------------------------------------------------- # Tensor used to determine if a nan/if has happend. # Any non-zero value indicates inf/nan. # Note that we keep this for the cases that grad scaler is none. # We still record nan/inf if we have a bfloat16 with a grad scaler. # 用于记录【所有gpu上】是否发生了梯度溢出的情况, # 值为0时表示所有gpu上都没有梯度溢出情况;值不为0时表示至少1块gpu上出现梯度溢出情况 # --------------------------------------------------------------------- if self.grad_scaler: self.found_inf = torch.cuda.FloatTensor([0.0]) # --------------------------------------------------------------------- # Dummy tensor needed for apex multi-apply tensor. # For bfloat, we don't have multi-tensor apply and for now # we set it to none so the multi-tensor apply gets ignored. # 这是在定义apex的multi_tensor_applier函数的其中一个参数, # 该函数的目的是在fp16的精度下让数据复制更有效率(在一个kernel内完成复制) # bf16下还没有相关的优化操作。 # 如果不使用该函数,则正常用tensor.copy_(src)的方式做复制 # --------------------------------------------------------------------- if bf16: self._dummy_overflow_buf = None else: self._dummy_overflow_buf = torch.cuda.IntTensor([0]) # In case grad scaler is not passed, define the unity scale. if self.grad_scaler is None: self._scale_one = torch.cuda.FloatTensor([1.0]) # ====================== # main parameter stuff # ====================== # --------------------------------------------------------------------- # Three groups of parameters: # float16_groups: original float16 parameters # fp32_from_float16_groups: fp32 copy of float16 parameters # fp32_from_fp32_groups: original fp32 parameters # --------------------------------------------------------------------- self.float16_groups = [] # 装原始就是fp16/bf16的权重 self.fp32_from_float16_groups = [] # 装从fp16拷贝并转换而来的fp32权重 self.fp32_from_fp32_groups = [] # 装原始就是fp32的权重 # For all the groups in the original optimizer: for param_group in self.optimizer.param_groups: float16_params_this_group = [] fp32_params_this_group = [] fp32_from_float16_params_this_group = [] # For all the parameters in this group: for i, param in enumerate(param_group["params"]): if param.requires_grad: # float16 params: if param.type() in [ "torch.cuda.HalfTensor", "torch.cuda.BFloat16Tensor", ]: # 原始就是fp16/bf16的权重 float16_params_this_group.append(param) # --------------------------------------------------------------------- # Create a copy # 将原始就是fp16/bf16的权重转变为fp32的形式 # detach:新的权重脱离了计算图(requires_grad = False),但是和旧权重共享内存 # clone:开辟了新的内存 # float:转成fp32 # 最终实现:从fp16/bf16转成fp32,同时脱离计算图,同时开辟新内存的目的。 # 单独用detach无法开辟新内存,单独用clone无法脱离计算图 # ref:https://blog.csdn.net/winycg/article/details/100813519 # --------------------------------------------------------------------- main_param = param.detach().clone().float() # --------------------------------------------------------------------- # Copy tensor model parallel attributes. # 将tp并行相关的tensor属性拷贝到这些转换而来的fp32上 # 对此有疑惑的,可以参考Megatron源码解读第一篇:分布式环境初始化 # --------------------------------------------------------------------- mpu.copy_tensor_model_parallel_attributes(main_param, param) # --------------------------------------------------------------------- # 另外,将是否是输出层WE的情况拷贝到转换而来的fp32上 #(复习一下,shared这个属性只在pp度非0时的输出层WE才有) # 参考Megatron源码解读第二篇:模型并行,Word Embedding相关代码 # --------------------------------------------------------------------- if hasattr(param, "shared"): main_param.shared = param.shared # --------------------------------------------------------------------- # Replace the optimizer params with the new fp32 copy. # 将optimizer中的参数用fp32代替 # --------------------------------------------------------------------- param_group["params"][i] = main_param fp32_from_float16_params_this_group.append(main_param) # Reset existing state dict key to the new main param. if param in self.optimizer.state: self.optimizer.state[main_param] = self.optimizer.state.pop( param ) # --------------------------------------------------------------------- # fp32 params. # 原始是fp32的权重 # --------------------------------------------------------------------- elif param.type() == "torch.cuda.FloatTensor": fp32_params_this_group.append(param) param_group["params"][i] = param else: raise TypeError( "Wrapped parameters must be one of " "torch.cuda.FloatTensor, " "torch.cuda.HalfTensor, or " "torch.cuda.BFloat16Tensor. " "Received {}".format(param.type()) ) self.float16_groups.append(float16_params_this_group) self.fp32_from_float16_groups.append(fp32_from_float16_params_this_group) self.fp32_from_fp32_groups.append(fp32_params_this_group) # Leverage state_dict() and load_state_dict() to # recast preexisting per-param state tensors self.optimizer.load_state_dict(self.optimizer.state_dict()) def zero_grad(self, set_to_none=True): """We only need to zero the model related parameters, i.e., float16_groups & fp32_from_fp32_groups. 我们只对参与模型训练的那部分参数做梯度计算(同理做梯度清0), 对optimizer中存储的fp32的states不做梯度计算/清理处理,这部分states只用于做更新 """ for group in self.float16_groups: _zero_grad_group_helper(group, set_to_none) for group in self.fp32_from_fp32_groups: _zero_grad_group_helper(group, set_to_none) def get_loss_scale(self): if self.grad_scaler is None: return self._scale_one return self.grad_scaler.scale def _copy_model_grads_to_main_grads(self): """ 将model grads拷贝到main grads上去 """ # This only needs to be done for the float16 group. for model_group, main_group in zip( self.float16_groups, self.fp32_from_float16_groups ): for model_param, main_param in zip(model_group, main_group): if self.params_have_main_grad: # 相关定义见4.1 # 将梯度从fp16转为fp32 main_param.grad = model_param.main_grad.float() else: if model_param.grad is not None: main_param.grad = model_param.grad.float() # For fp32 grads, we need to reset the grads to main grad. if self.params_have_main_grad: for model_group in self.fp32_from_fp32_groups: for model_param in model_group: model_param.grad = model_param.main_grad def _unscale_main_grads_and_check_for_nan(self): main_grads = [] # fp32 params fromm float16 ones. for main_group in self.fp32_from_float16_groups: for main_param in main_group: if main_param.grad is not None: main_grads.append(main_param.grad.data) # Append fp32 parameters. for main_group in self.fp32_from_fp32_groups: for main_param in main_group: if main_param.grad is not None: main_grads.append(main_param.grad.data) # --------------------------------------------------------------------- # Reset found inf. # 用于记录全局(所有的gpu上)是否存在梯度溢出的情况 # self.found_inf为0,则不存在梯度溢出;否则至少1块gpu存在梯度溢出情况 # 如果存在梯度溢出,将会跳过该轮step()更新 # --------------------------------------------------------------------- self.found_inf.fill_(0.0) # --------------------------------------------------------------------- # Unscale and set found inf/nan # 这里做两件事: # 1、判断scale后是否存在梯度溢出 # 2、unscale梯度,将梯度恢复正常值,为更新做准备 # --------------------------------------------------------------------- torch._amp_foreach_non_finite_check_and_unscale_( main_grads, self.found_inf, self.grad_scaler.inv_scale ) # --------------------------------------------------------------------- # Update across all model parallel instances. # 检查全局上是否有梯度溢出情况 # --------------------------------------------------------------------- torch.distributed.all_reduce( self.found_inf, op=torch.distributed.ReduceOp.MAX, group=mpu.get_model_parallel_group(), ) # Check for nan. found_inf_flag = self.found_inf.item() > 0 return found_inf_flag def _get_model_and_main_params_data_float16(self): """ 得到原始fp16的权重和由fp16转变而来的fp32的权重 """ model_data = [] main_data = [] for model_group, main_group in zip( self.float16_groups, self.fp32_from_float16_groups ): for model_param, main_param in zip(model_group, main_group): model_data.append(model_param.data) main_data.append(main_param.data) return model_data, main_data def _copy_main_params_to_model_params(self): # Only needed for the float16 params. model_data, main_data = self._get_model_and_main_params_data_float16() _multi_tensor_copy_this_to_that( this=main_data, that=model_data, overflow_buf=self._dummy_overflow_buf ) def _copy_model_params_to_main_params(self): # Only needed for the float16 params. model_data, main_data = self._get_model_and_main_params_data_float16() _multi_tensor_copy_this_to_that( this=model_data, that=main_data, overflow_buf=self._dummy_overflow_buf ) def reload_model_params(self): self._copy_model_params_to_main_params() @torch.no_grad() def step(self): """ 重写optimizer中的step()操作,也就是用梯度更新权重这一部分 """ timers = get_timers() # --------------------------------------------------------------------- # Copy gradients from model params to main params. # 1、首先,把model grads转变成fp32的形式,并拷贝到main_grads上 # --------------------------------------------------------------------- timers("optimizer-copy-to-main-grad").start() self._copy_model_grads_to_main_grads() timers("optimizer-copy-to-main-grad").stop() # --------------------------------------------------------------------- # Do unscale, check for inf, and update grad scaler only for # the case that grad scaler is provided. # 2、如果我们做过loss scale # --------------------------------------------------------------------- if self.grad_scaler: # --------------------------------------------------------------------- # Unscale and check for inf/nan. # 遍历【每块】GPU,检查是否存在梯度溢出情况,并将main_grads还原成未scale的值 # --------------------------------------------------------------------- timers("optimizer-unscale-and-check-inf").start() found_inf_flag = self._unscale_main_grads_and_check_for_nan() timers("optimizer-unscale-and-check-inf").stop() # --------------------------------------------------------------------- # We are done with scaling gradients # so we can update the loss scale. # 根据溢出的检查结果,动量更新loss scale,原理见3.3(3) # 如果是常数scaler,则update后scale不变; # 如果是动态scaler,则会根据scale前梯度是否存在nan/inf来动态调整scale的大小 # --------------------------------------------------------------------- self.grad_scaler.update(found_inf_flag) # --------------------------------------------------------------------- # If we found inf/nan, skip the update. # 一旦存在梯度nan/inf的情况,则跳过这个step,不做权重更新 # return的三个值分别表示:是否更新成功,clip中的total_norm(见3.4),值为0的梯度数 # --------------------------------------------------------------------- if found_inf_flag: return False, None, None # --------------------------------------------------------------------- # Clip the main gradients. # 3、梯度剪裁 # --------------------------------------------------------------------- timers("optimizer-clip-main-grad").start() grad_norm = None if self.clip_grad > 0.0: # --------------------------------------------------------------------- # 这是对main grad做inplace的剪裁,grad_norm返回的是total_norm # clip_grad_norm的实现就不细讲啦,大家自己看代码细节即可 # --------------------------------------------------------------------- grad_norm = self.clip_grad_norm(self.clip_grad) timers("optimizer-clip-main-grad").stop() # --------------------------------------------------------------------- # count the zeros in the grads # 4、统计为0的梯度数 # --------------------------------------------------------------------- num_zeros_in_grad = self.count_zeros() if self.log_num_zeros_in_grad else None # --------------------------------------------------------------------- # Step the optimizer. # 5、正常更新optimizer, # 由于我们在__init__中就将optimizer的param从fp16指向了fp32, # 所以这里更新的是fp32(main_param)的结果 # --------------------------------------------------------------------- self.optimizer.step() # --------------------------------------------------------------------- # Update params from main params. # 6、将main_param拷贝给model_param # 有了更新完的fp32权重,就能做下一轮训练了,所以这时我们需要用新的fp32权重 # 去更新一次fp16权重 # --------------------------------------------------------------------- timers("optimizer-copy-main-to-model-params").start() self._copy_main_params_to_model_params() timers("optimizer-copy-main-to-model-params").stop() # --------------------------------------------------------------------- # Successful update. # 是否成功update、total_norm,值为0的梯度个数 # --------------------------------------------------------------------- return True, grad_norm, num_zeros_in_grad def state_dict(self): state_dict = {} state_dict["optimizer"] = self.optimizer.state_dict() if self.grad_scaler: state_dict["grad_scaler"] = self.grad_scaler.state_dict() state_dict["fp32_from_fp16_params"] = self.fp32_from_float16_groups return state_dict def load_state_dict(self, state_dict): # Optimizer. optimizer_key = "optimizer" if optimizer_key not in state_dict: optimizer_key = "optimizer_state_dict" print_rank_0( "***WARNING***loading optimizer from " "an old checkpoint ..." ) self.optimizer.load_state_dict(state_dict[optimizer_key]) # Grad scaler. if "grad_scaler" not in state_dict: print_rank_0( "***WARNING***found an old checkpoint, will not " "load grad scaler ..." ) else: if self.grad_scaler: self.grad_scaler.load_state_dict(state_dict["grad_scaler"]) else: print_rank_0( "***WARNING***fould the grad scaler in the " "checkpoint but it is None in the class. " "Skipping loading grad scaler ..." ) # Copy data for the main params. fp32_from_float16_params_key = "fp32_from_fp16_params" if fp32_from_float16_params_key not in state_dict: fp32_from_float16_params_key = "fp32_from_fp16" for current_group, saved_group in zip( self.fp32_from_float16_groups, state_dict[fp32_from_float16_params_key] ): for current_param, saved_param in zip(current_group, saved_group): current_param.data.copy_(saved_param.data) -
__init__()方法可理解为混合精度训练的初始化准备环节,核心目标是:从以 fp16/bf16 精度存储的模型中,分离并拷贝出一份 fp32 精度的权重副本,为后续梯度更新做准备 -
在原始的
self.optimizer.param_groups中,存储的是模型的核心权重参数,其中大部分为 fp16/bf16 精度,但并非全部 —— 这是因为 BN(Batch Normalization)、LN(Layer Normalization)等层的权重若全程使用 fp16 训练,会导致显著的精度损失,进而引发训练不稳定,因此这类权重会始终以 fp32 精度保存 -
基于这一前提,
__init__()方法主要完成以下三步核心操作- 遍历
self.optimizer.param_groups中的所有权重,按精度分类存储:- 将 fp16/bf16 精度的权重筛选出来,存入列表
self.float16_groups; - 将原本就保持 fp32 精度的 BN/LN 相关权重,存入列表
self.fp32_from_fp32_groups
- 将 fp16/bf16 精度的权重筛选出来,存入列表
- 对
self.float16_groups中的 fp16/bf16 权重做精度转换 + 拷贝:将其转换为 fp32 精度后,存入列表self.fp32_from_float16_groups - 这里需要明确 Megatron 代码中的命名规则:
- fp16/bf16 权重被称为
model_param(模型前向 / 反向计算时使用的参数); - 拷贝后的 fp32 权重被称为
main_param(真正用于梯度更新、最终保存的核心参数)
- fp16/bf16 权重被称为
- 将
self.optimizer.param_groups指向的权重,从原本的 fp16/bf16 替换为新生成的 fp32 权重 - 这样做的目的是:当调用优化器的
step()方法执行梯度更新时,实际更新的是 fp32 精度的main_param,保证更新过程的数值稳定性
- 遍历
-
这里需要重点拆解从 fp16 复制 fp32 权重的核心代码:
main_param = param.detach().clone().float() -
这行代码中
detach()和clone()是缺一不可的,我们可以分别分析只使用其中一个的问题,以及两者结合的原因- 只使用 clone () 的问题
clone()的作用是深拷贝:会开辟新的内存空间,完整复制原参数的数值,生成一个独立的张量- 克隆后的张量仍保留在计算图中,其
requires_grad=True(继承原参数的梯度属性) - 这会导致反向传播时,框架会试图对这份 fp32 的
main_param计算梯度 —— 但这与混合精度训练的逻辑完全冲突 - 根据混合精度流程图,梯度是由 fp16 的
model_param在前向 / 反向计算中生成的,main_param只负责接收转换后的梯度进行更新,本身不参与梯度计算 - 若
main_param参与梯度计算,会造成梯度重复计算、计算图混乱,最终导致训练数值错误或显存爆炸
- 只使用 detach () 的问题
detach()的作用是脱离计算图:会让张量与原计算图断开关联,requires_grad=False,不再参与梯度计算- 但仅用
detach()存在关键问题: detach()不会开辟新内存,返回的张量与原 fp16 的param共享同一块内存空间- 这意味着修改
main_param(如梯度更新)时,原 fp16 的param也会被同步修改 —— 而我们的核心目标是让 fp32 权重独立存储、独立更新,与 fp16 权重解耦,因此仅detach()无法满足 “独立副本” 的需求
- 两者结合才能同时满足两个核心要求:
- 先
detach():让张量脱离计算图,requires_grad=False,确保 fp32 权重不参与梯度计算,只接收更新; - 再
clone():在脱离计算图的基础上,开辟新内存生成独立副本,保证 fp32 权重与原 fp16 权重物理隔离,互不影响; - 最后
.float():将拷贝后的张量精度转换为 fp32,得到真正独立、无梯度计算、高精度的main_param
- 先
- 只使用 clone () 的问题
-
step 方法
- 它是混合精度训练的核心执行环节,定义了如何将 fp16 权重计算出的梯度,转换并应用到 fp32 权重的更新上
- 在 Megatron 这类分布式训练框架中,模型被拆分到多块 GPU 上:
- 每块 GPU 先独立检查自己负责的参数梯度是否溢出;
- 通过
all_reduce操作汇总所有 GPU 的溢出状态(只要有一块 GPU 溢出,结果就为 “溢出”); - 若判定溢出,直接清空所有梯度、放弃本轮
step()更新 —— 这是为了保证所有 GPU 训练状态的一致性,避免部分卡更新、部分卡不更新导致模型参数错乱